

Show notes
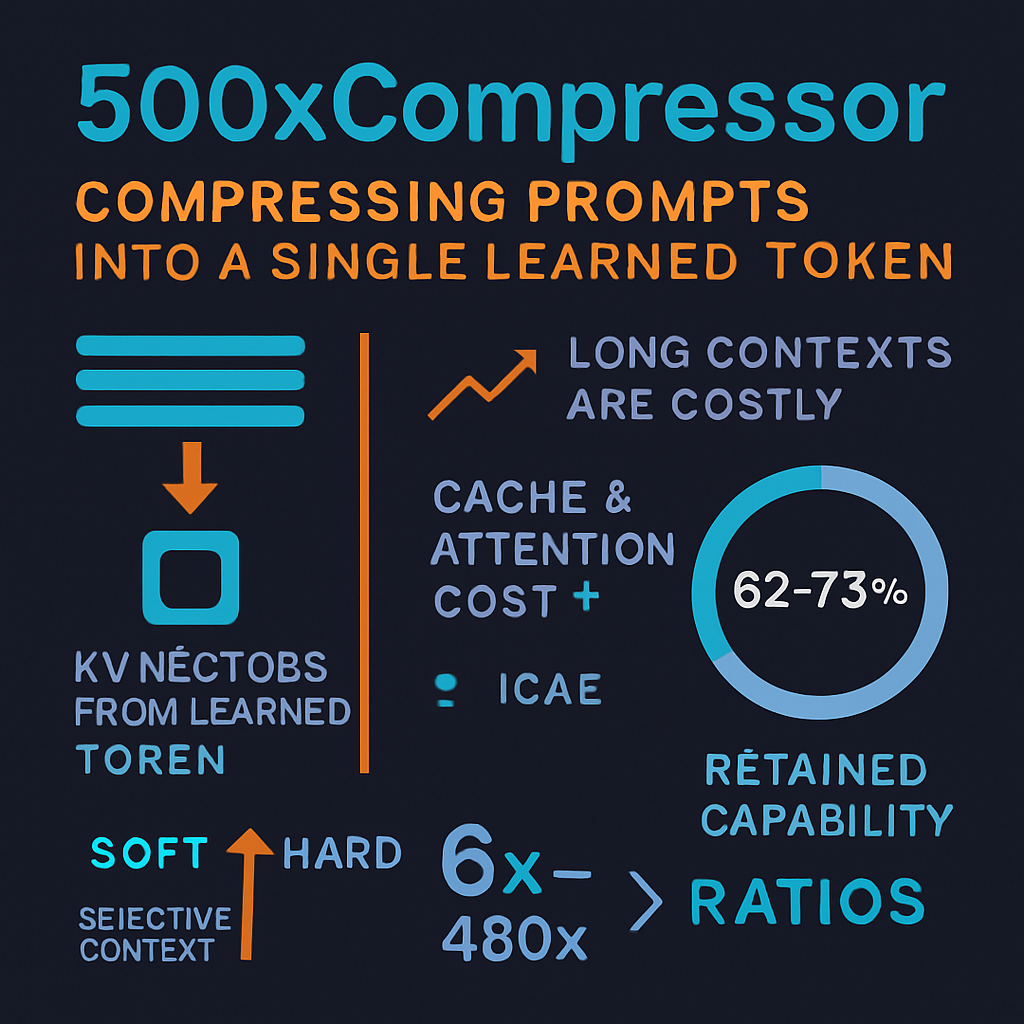
This episode examines "500xCompressor," a soft prompt compression method that squeezes hundreds of tokens of context into as little as a single learned token. A frozen Llama-3-8B decoder then answers questions from that token's key-value (KV) vectors alone. It covers why long contexts are costly (KV cache memory and attention cost grow with length). It also contrasts hard compression, which deletes text (Selective Context, LLMLingua), with soft approaches (gist tokens, AutoCompressor, ICAE, xRAG). The discussion walks through how a LoRA-adapted encoder and autoencoder-style regeneration pretraining produce those KV values, and what the headline 6x–480x ratios and 62–73% retained capability actually measure. The hosts also scrutinize the evaluation: arXiv abstracts from early 2024 are used to avoid pretraining leakage, and F1 versus Exact Match are explained. Listeners get a critical look at whether KV beats embeddings and whether the benchmark can be trusted.
Sources:
1. 500xCompressor: Generalized Prompt Compression for Large Language Models — Zongqian Li, Yixuan Su, Nigel Collier, 2024
http://arxiv.org/abs/2408.03094v1
2. Compressing Context to Enhance Inference Efficiency of Large Language Models (Selective Context) — Li, Dong, Guerin, Lin, 2023
https://scholar.google.com/scholar?q=Compressing+Context+to+Enhance+Inference+Efficiency+of+Large+Language+Models+%28Selective+Context%29
3. Learning to Compress Prompts with Gist Tokens — Mu, Li, Goodman, 2023
https://scholar.google.com/scholar?q=Learning+to+Compress+Prompts+with+Gist+Tokens
4. Adapting Language Models to Compress Contexts (AutoCompressor) — Chevalier, Wettig, Ajith, Chen, 2023
https://scholar.google.com/scholar?q=Adapting+Language+Models+to+Compress+Contexts+%28AutoCompressor%29
5. xRAG: Extreme Context Compression for Retrieval-augmented Generation with One Token — Cheng et al., 2024
https://scholar.google.com/scholar?q=xRAG%3A+Extreme+Context+Compression+for+Retrieval-augmented+Generation+with+One+Token
6. In-context Autoencoder for Context Compression in a Large Language Model (ICAE) — Ge, Jing, Wang, Wang, Chen, Wei, 2024
https://scholar.google.com/scholar?q=In-context+Autoencoder+for+Context+Compression+in+a+Large+Language+Model+%28ICAE%29
7. Prefix-Tuning: Optimizing Continuous Prompts for Generation — Li, Liang, 2021
https://scholar.google.com/scholar?q=Prefix-Tuning%3A+Optimizing+Continuous+Prompts+for+Generation
8. Cartridges: Lightweight and general-purpose long context representations via self-study — Eyuboglu et al., 2025
https://scholar.google.com/scholar?q=Cartridges%3A+Lightweight+and+general-purpose+long+context+representations+via+self-study
9. Function Vectors in Large Language Models — Todd et al., 2024
https://scholar.google.com/scholar?q=Function+Vectors+in+Large+Language+Models
10. Efficient Streaming Language Models with Attention Sinks (StreamingLLM) — Xiao et al…
