

Beschrijving
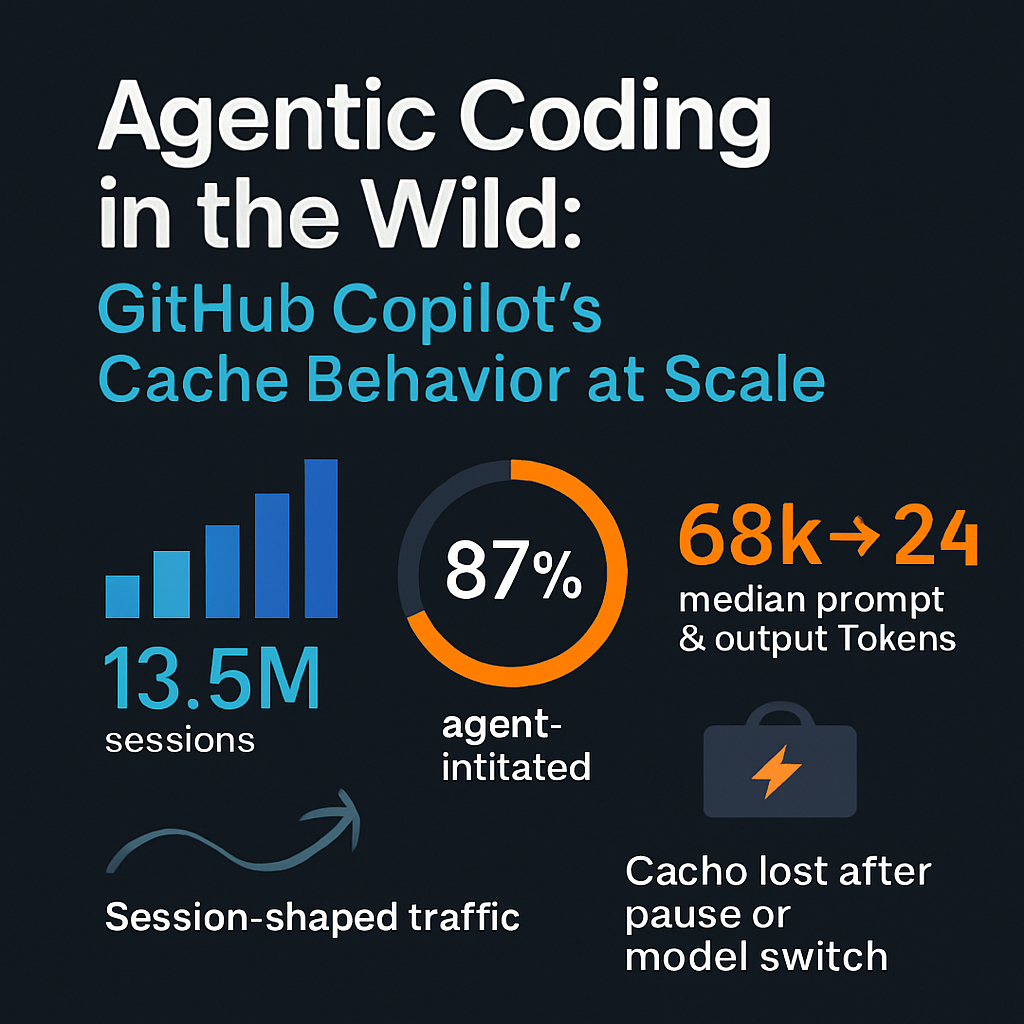
This episode examines a production-scale characterization of GitHub Copilot's coding agent, built on sampled client-side telemetry from one week in June 2026 (13.5 million sessions and 760 million LLM calls, though some totals are inconsistent). It argues that agent traffic is session-shaped rather than stateless chat. About 87% of LLM calls are agent-initiated, the median call carries roughly 68,000 prompt tokens to produce about 247 output tokens, and the human appears only at turn boundaries. The discussion explains how prefix caching should give very high reuse inside a turn, and why the cache is lost after a pause, a model switch, or context compaction. It also separates "container idle" from "KV-cache idle", which suggests turn boundaries are the natural point to reclaim resources. The episode places the work alongside prior agentic KV-retention research and serverless idle-time studies. Listeners get a clear framework for why request-level scheduling and plain LRU eviction fall short for agent workloads, along with caveats about inferring server behavior from client data alone.
Sources:
1. Agentic Coding in the Wild: Characterizing GitHub Copilot Traces at Production Scale — Banruo Liu, Haoran Qiu, Íñigo Goiri, Rodrigo Fonseca, Ricardo Bianchini, Esha Choukse, 2026
http://arxiv.org/abs/2608.00101v1
2. SWE-bench: Can Language Models Resolve Real-World GitHub Issues? — Carlos E. Jimenez, John Yang, Alexander Wettig, Shunyu Yao, Kexin Pei, Ofir Press, Karthik Narasimhan, 2023 (ICLR 2024)
https://scholar.google.com/scholar?q=SWE-bench%3A+Can+Language+Models+Resolve+Real-World+GitHub+Issues%3F
3. Splitwise: Efficient Generative LLM Inference Using Phase Splitting — Pratyush Patel, Esha Choukse, Chaojie Zhang, Íñigo Goiri, et al. (Microsoft), 2023 (ISCA 2024)
https://scholar.google.com/scholar?q=Splitwise%3A+Efficient+Generative+LLM+Inference+Using+Phase+Splitting
4. BurstGPT: A Real-world Workload Dataset to Optimize LLM Serving Systems — Yuxin Wang, Yuhan Chen, Zeyu Li, et al., 2024
https://scholar.google.com/scholar?q=BurstGPT%3A+A+Real-world+Workload+Dataset+to+Optimize+LLM+Serving+Systems
5. Mooncake: A KVCache-centric Disaggregated Architecture for LLM Serving — Ruoyu Qin, Zheng Li, Weiran He, et al. (Moonshot AI), 2024 (FAST 2025 best paper)
https://scholar.google.com/scholar?q=Mooncake%3A+A+KVCache-centric+Disaggregated+Architecture+for+LLM+Serving
6. MemGPT: Towards LLMs as Operating Systems — Charles Packer, Sarah Wooders, Kevin Lin, Vivian Fang, Shishir G. Patil, Ion Stoica, Joseph E. Gonzalez, 2023
https://scholar.google.com/scholar?q=MemGPT%3A+Towards+LLMs+as+Operating+Systems
7. Lost in the Middle: How Language Models Use Long Contexts — Nelson F. Liu, Kevin Lin, John Hewitt, Ashwin Paranjape, Michele Bevilacqua, Fabio Petroni, Percy Liang, 2023 (TACL 2024)
https://scholar.google.com/scholar?q=Lost+in+the+Middle%3A+How+Language+Models+Use+Long+Contexts
8. LLMLingua: Compressing Prompts for Accelerated Inference of Large Language…
