

Show notes
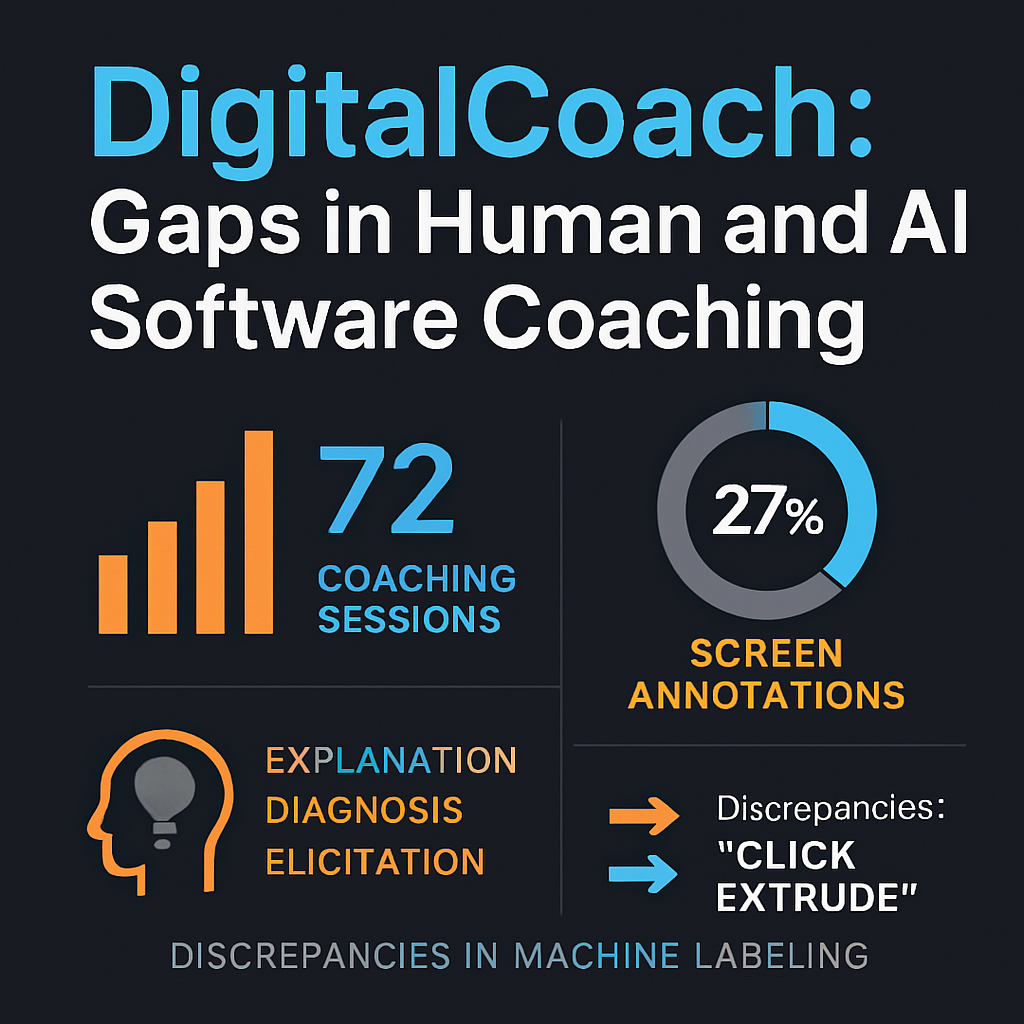
This episode examines DIGITALCOACH, a dataset of 72 human coaching sessions (22,752 dialogue turns across Excel, FL Studio, Blender, Figma and Onshape) built to test whether multimodal models can coach novices through real software rather than just automate it. It separates what coaches say (dialogue acts), how they teach (methods drawn from cognitive apprenticeship, such as explanation, diagnosis and elicitation), and how they tie guidance to the learner's screen. Human coaches orient and explain as well as direct, and about 27% of their turns carry annotations drawn on the learner's screen. Current models mostly give bare instructions like "click Extrude". The discussion also questions how far the machine-labeled distributions can be trusted, since the labels were validated on only 200 utterances. It then sets up the offline next-utterance comparison and the live study of whether novices actually learn.
Sources:
1. DigitalCoach: Gaps in Human and AI Software Coaching
https://arxiv.org/pdf/2606.31980
2. OSWorld: Benchmarking Multimodal Agents for Open-Ended Tasks in Real Computer Environments — Tianbao Xie, Danyang Zhang, Jixuan Chen, et al., 2024
https://scholar.google.com/scholar?q=OSWorld%3A+Benchmarking+Multimodal+Agents+for+Open-Ended+Tasks+in+Real+Computer+Environments
3. Mind2Web: Towards a Generalist Agent for the Web — Xiang Deng, Yu Gu, Boyuan Zheng, et al., 2023
https://scholar.google.com/scholar?q=Mind2Web%3A+Towards+a+Generalist+Agent+for+the+Web
4. Principles of Mixed-Initiative User Interfaces — Eric Horvitz, 1999
https://scholar.google.com/scholar?q=Principles+of+Mixed-Initiative+User+Interfaces
5. Executing Instructions in Situated Collaborative Interactions — Alane Suhr, Claudia Yan, Jack Schluger, Stanley Yu, Hadi Khader, Marwa Mouallem, Iris Zhang, Yoav Artzi, 2019
https://scholar.google.com/scholar?q=Executing+Instructions+in+Situated+Collaborative+Interactions
6. Making the V in VQA Matter: Elevating the Role of Image Understanding in Visual Question Answering — Yash Goyal, Tejas Khot, Douglas Summers-Stay, Dhruv Batra, Devi Parikh, 2017
https://scholar.google.com/scholar?q=Making+the+V+in+VQA+Matter%3A+Elevating+the+Role+of+Image+Understanding+in+Visual+Question+Answering
7. SeeClick: Harnessing GUI Grounding for Advanced Visual GUI Agents — Kanzhi Cheng, Qiushi Sun, Yougang Chu, et al., 2024
https://scholar.google.com/scholar?q=SeeClick%3A+Harnessing+GUI+Grounding+for+Advanced+Visual+GUI+Agents
8. Visual Dialog — Abhishek Das, Satwik Kottur, Khushi Gupta, et al., 2017
https://scholar.google.com/scholar?q=Visual+Dialog
9. Don't Just Assume; Look and Answer: Overcoming Priors for Visual Question Answering — Aishwarya Agrawal, Dhruv Batra, Devi Parikh, Aniruddha Kembhavi, 2018
https://scholar.google.com/scholar?q=Don%27t+Just+Assume%3B+Look+and+Answer%3A+Overcoming+Priors+for+Visual+Question+Answering
10. Learning from Human Tutoring — Michelene T. H. Chi, Stephanie A. Siler, Heisawn Jeong, Takashi Yamauchi, Robert G…


