

Jakson kuvaus
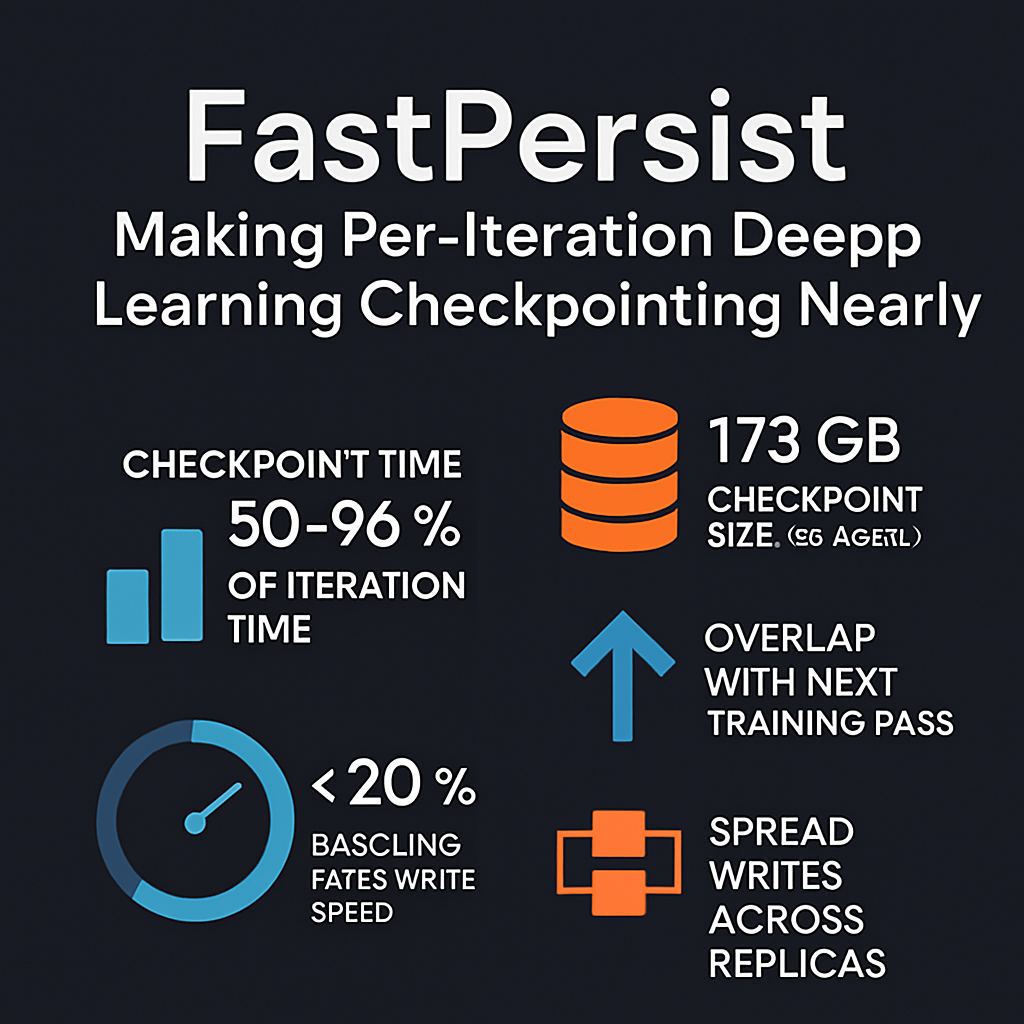
This episode examines FastPersist, a DeepSpeed paper on making deep learning model checkpointing fast enough to save every training iteration. It lays out why checkpoint time has grown to 50–96% of iteration time as data parallelism scaled, and why a checkpoint is so large: mixed-precision Adam state works out to about 14 bytes per parameter, or 173 GB for a 13B model. The discussion traces the slowness to torch.save issuing small, unaligned writes. That leaves NVMe drives well below peak, with the baseline reaching under 20% of the 24.8 GB/s a RAID-0 array can deliver. It also covers the structural opportunity to overlap checkpointing with the next forward and backward passes, and to spread writes across data-parallel replicas that hold identical state. The episode compares the approach with CheckFreq, Check-N-Run and Gemini, and it questions whether checkpointing every iteration is the right target. It also notes what the paper leaves out, such as SSD write-cache behavior and flash wear.
Sources:
1. FastPersist: Accelerating Model Checkpointing in Deep Learning — Guanhua Wang, Olatunji Ruwase, Bing Xie, Yuxiong He, 2024
http://arxiv.org/abs/2406.13768
2. CheckFreq: Frequent, Fine-Grained DNN Checkpointing — Jayashree Mohan, Amar Phanishayee, Vijay Chidambaram, 2021
https://scholar.google.com/scholar?q=CheckFreq%3A+Frequent%2C+Fine-Grained+DNN+Checkpointing
3. Gemini: Fast Failure Recovery in Distributed Training with In-Memory Checkpoints — Zhuang Wang, Zhen Jia, Shuai Zheng, Zhen Zhang, Xinwei Fu, T. S. Eugene Ng, Yida Wang, 2023
https://scholar.google.com/scholar?q=Gemini%3A+Fast+Failure+Recovery+in+Distributed+Training+with+In-Memory+Checkpoints
4. Check-N-Run: A Checkpointing System for Training Deep Learning Recommendation Models — Assaf Eisenman, Kiran Kumar Matam, Steven Ingram, Dheevatsa Mudigere, Raghuraman Krishnamoorthi, Krishnakumar Nair, Misha Smelyanskiy, Murali Annavaram, 2022
https://scholar.google.com/scholar?q=Check-N-Run%3A+A+Checkpointing+System+for+Training+Deep+Learning+Recommendation+Models
5. ByteCheckpoint: A Unified Checkpointing System for Large Foundation Model Development — Borui Wan, Mingji Han, Yiyao Sheng, Yanghua Peng, Haibin Lin, Mofan Zhang, Zhichao Lai, Menghan Yu, Junda Zhang, Zuquan Song, Xin Liu, Chuan Wu, 2024
https://scholar.google.com/scholar?q=ByteCheckpoint%3A+A+Unified+Checkpointing+System+for+Large+Foundation+Model+Development
6. ZeRO-Infinity: Breaking the GPU Memory Wall for Extreme Scale Deep Learning — Samyam Rajbhandari, Olatunji Ruwase, Jeff Rasley, Shaden Smith, Yuxiong He, 2021
https://scholar.google.com/scholar?q=ZeRO-Infinity%3A+Breaking+the+GPU+Memory+Wall+for+Extreme+Scale+Deep+Learning
7. Characterizing Deep Learning Training Workloads on Alibaba-PAI / Understanding Data Storage and Ingestion for Large-Scale Deep Recommendation Model Training — Mark Zhao, Niket Agarwal, Aarti Basant, Buğra Gedik, Satadru Pan, Mustafa Ozdal, Rakesh Komuravelli, Jerry Pan, Tianshu Bao, Haowei Lu…
