

Notas del episodio
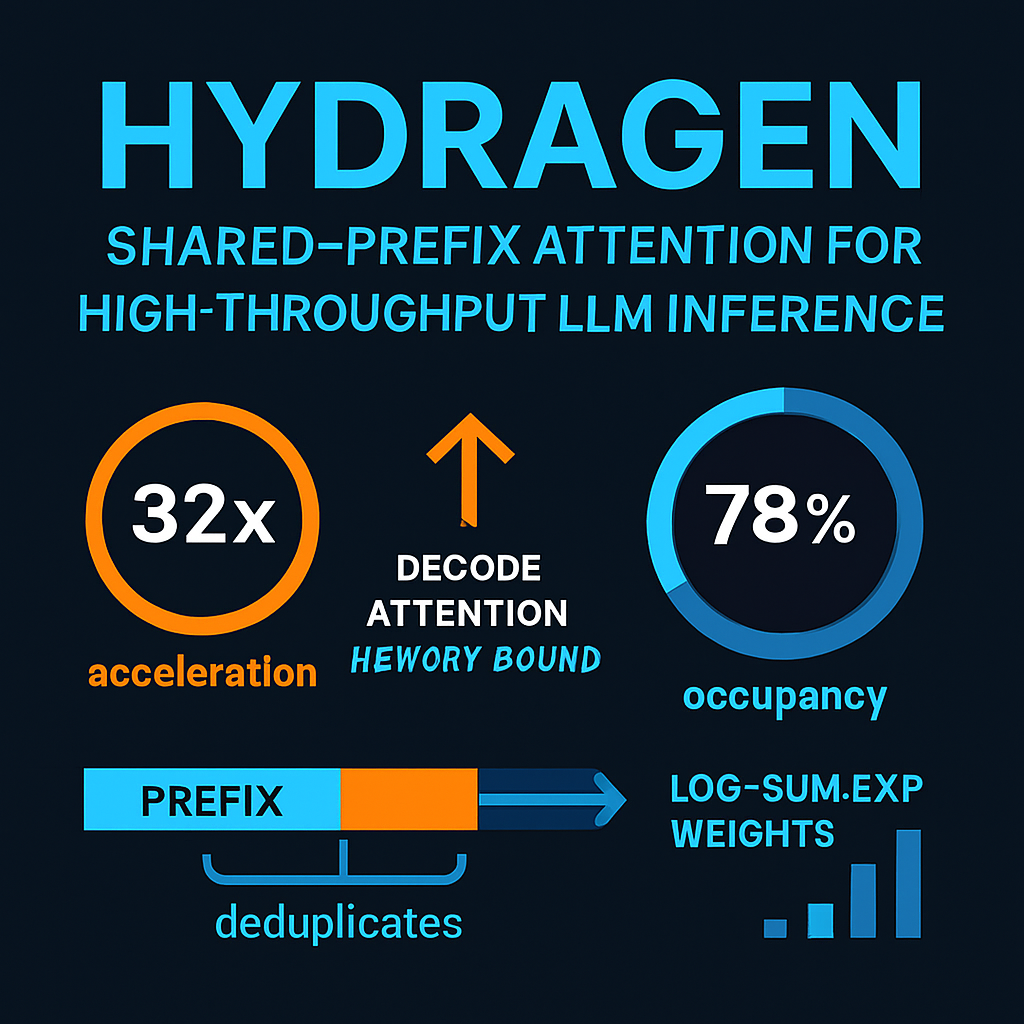
This episode examines Hydragen, a technique for speeding up LLM inference when many requests share a long prompt prefix, and asks how much of its claimed 32x end-to-end throughput gain comes from the idea and how much from the baseline. It explains why decode attention is memory-bound: each sequence runs a matrix-vector product against its own KV cache, which leaves tensor cores idle and makes batching unable to help. The central argument is that vLLM's PagedAttention deduplicates the storage of shared prefixes but not the reads, so every sequence still streams the full prefix from memory. Hydragen targets those reads by splitting attention into prefix and suffix parts and combining them using log-sum-exp weights. The authors present this as exact attention built on the FlashAttention family, with no approximation. The episode ends as the hosts ask why splitting the softmax is still exact.
Sources:
1. Hydragen: High-Throughput LLM Inference with Shared Prefixes — Jordan Juravsky, Bradley Brown, Ryan Ehrlich, Daniel Y. Fu, Christopher Ré, Azalia Mirhoseini, 2024
http://arxiv.org/abs/2402.05099
2. Hydragen: High-Throughput LLM Inference with Shared Prefixes — Jordan Juravsky, Bradley Brown, Ryan Ehrlich, Daniel Y. Fu, Christopher Ré, Azalia Mirhoseini, 2024
https://scholar.google.com/scholar?q=Hydragen%3A+High-Throughput+LLM+Inference+with+Shared+Prefixes
3. Cascade Inference: Memory Bandwidth Efficient Shared Prefix Batch Decoding (FlashInfer blog) and FlashInfer: Efficient and Customizable Attention Engine for LLM Inference Serving — Zihao Ye, Lequn Chen, Ruihang Lai, Wuwei Lin, Yineng Zhang, Stephanie Wang, Tianqi Chen, Baris Kasikci, Vinod Grover, Arvind Krishnamurthy, Luis Ceze, 2024 (blog) / 2025 (MLSys paper)
https://scholar.google.com/scholar?q=Cascade+Inference%3A+Memory+Bandwidth+Efficient+Shared+Prefix+Batch+Decoding+%28FlashInfer+blog%29+and+FlashInfer%3A+Efficient+and+Customizable+Attention+Engine+for+LLM+Inference+Serving
4. Bifurcated Attention: Accelerating Massively Parallel Decoding with Shared Prefixes in LLMs — Ben Athiwaratkun et al. (Amazon / AWS AI Labs), 2024
https://scholar.google.com/scholar?q=Bifurcated+Attention%3A+Accelerating+Massively+Parallel+Decoding+with+Shared+Prefixes+in+LLMs
5. ChunkAttention: Efficient Self-Attention with Prefix-Aware KV Cache and Two-Phase Partition — Lu Ye, Ze Tao, Yong Huang, Yang Li, 2024
https://scholar.google.com/scholar?q=ChunkAttention%3A+Efficient+Self-Attention+with+Prefix-Aware+KV+Cache+and+Two-Phase+Partition
6. Online normalizer calculation for softmax; Self-attention Does Not Need O(n^2) Memory; FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Maxim Milakov & Natalia Gimelshein (2018); Markus Rabe & Charles Staats (2021); Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré (2022), 2018 / 2021 /…
