

Episodebeskrivelse
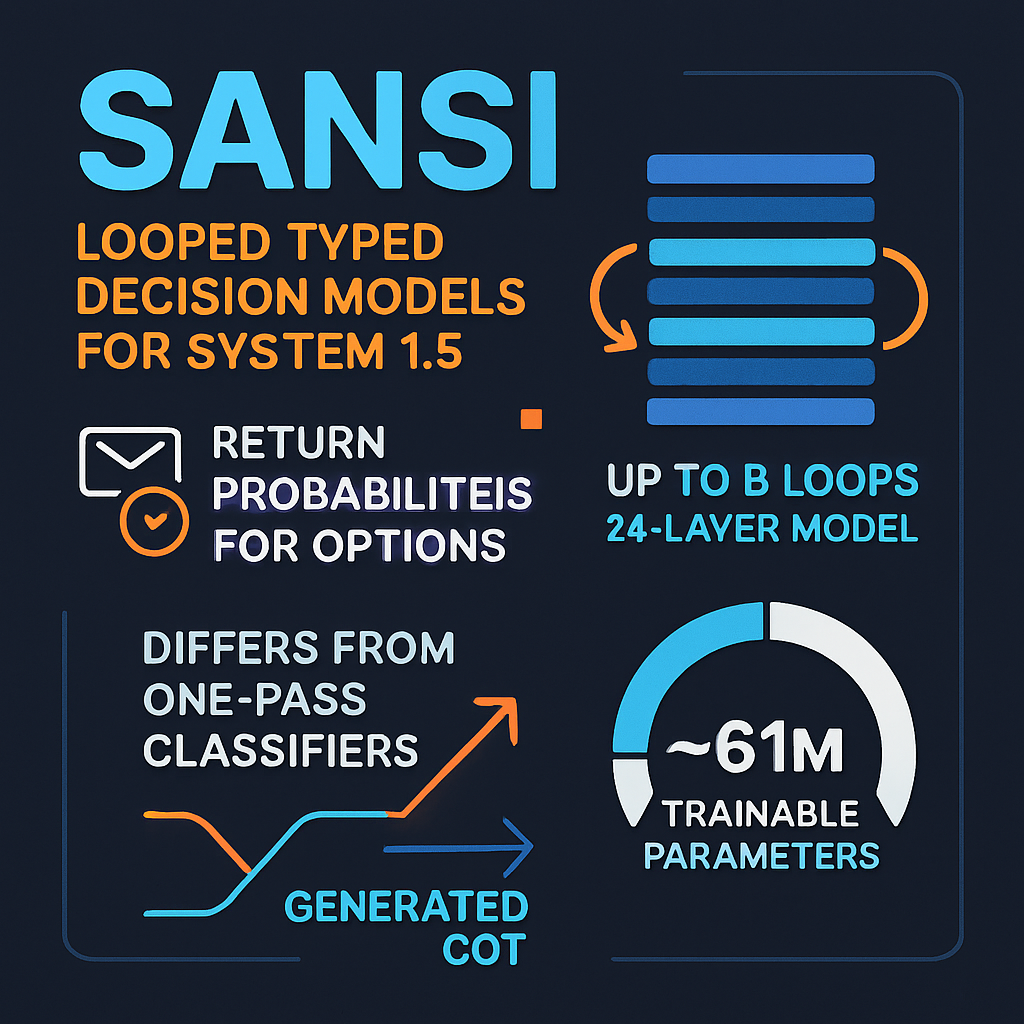
This episode examines SanSi, a small "typed decision" model that returns a probability for each caller-declared option (such as spam or not spam) in a single forward pass, with no generated text to parse. It explains how the model gets more computation by looping the same 24-layer stack up to eight times, with a readout after every loop, so one model can serve any budget from one loop to eight. The discussion covers how this "System 1.5" approach differs from one-pass classifiers and from generated chain-of-thought. It also covers the earlier work it builds on: Universal Transformers, adaptive computation time, and pre-trained looped models such as Ouro. On training, the model uses a frozen backbone with LoRA adapters (about 61 million trainable parameters) and a loss averaged across all loops. Supervising only the final loop dropped loop-1 accuracy to 35.6%, against 58.4% with per-loop training. The episode also raises caveats: the Kahneman-style labels are framing rather than evidence, the RL case study uses the judge's own probability as reward rather than a truly verifiable one, and it is unclear whether looping beats spending the same compute another way.
Sources:
1. SanSi: A Looped Typed Decision Model for System 1.5 Thinking — Shuyu Gan, Young-Jun Lee, Dongyeop Kang, 2026
http://arxiv.org/abs/2610.07730
2. SanSi: A Looped Typed Decision Model for System 1.5 Thinking — Shuyu Gan, Young-Jun Lee, Dongyeop Kang, 2026
https://scholar.google.com/scholar?q=SanSi%3A+A+Looped+Typed+Decision+Model+for+System+1.5+Thinking
3. Strictly Proper Scoring Rules, Prediction, and Estimation — Tilmann Gneiting, Adrian E. Raftery, 2007
https://scholar.google.com/scholar?q=Strictly+Proper+Scoring+Rules%2C+Prediction%2C+and+Estimation
4. On Calibration of Modern Neural Networks — Chuan Guo, Geoff Pleiss, Yu Sun, Kilian Q. Weinberger, 2017
https://scholar.google.com/scholar?q=On+Calibration+of+Modern+Neural+Networks
5. Generative Verifiers: Reward Modeling as Next-Token Prediction — Lunjun Zhang, Arian Hosseini, Hritik Bansal, Mehran Kazemi, Aviral Kumar, Rishabh Agarwal, 2024
https://scholar.google.com/scholar?q=Generative+Verifiers%3A+Reward+Modeling+as+Next-Token+Prediction
6. Universal Transformers — Mostafa Dehghani, Stephan Gouws, Oriol Vinyals, Jakob Uszkoreit, Łukasz Kaiser, 2019
https://scholar.google.com/scholar?q=Universal+Transformers
7. Scaling up Test-Time Compute with Latent Reasoning: A Recurrent Depth Approach — Jonas Geiping, Sean McLeish, Neel Jain, John Kirchenbauer, Siddharth Singh, Brian R. Bartoldson, Bhavya Kailkhura, Abhinav Bhatele, Tom Goldstein, 2025
https://scholar.google.com/scholar?q=Scaling+up+Test-Time+Compute+with+Latent+Reasoning%3A+A+Recurrent+Depth+Approach
8. Scaling Latent Reasoning via Looped Language Models (Ouro) — Rui-Jie Zhu et al., 2025
https://scholar.google.com/scholar?q=Scaling+Latent+Reasoning+via+Looped+Language+Models+%28Ouro%29
9. Adaptive Computation Time for Recurrent Neural Networks — Alex Graves…

