

Episodebeskrivelse
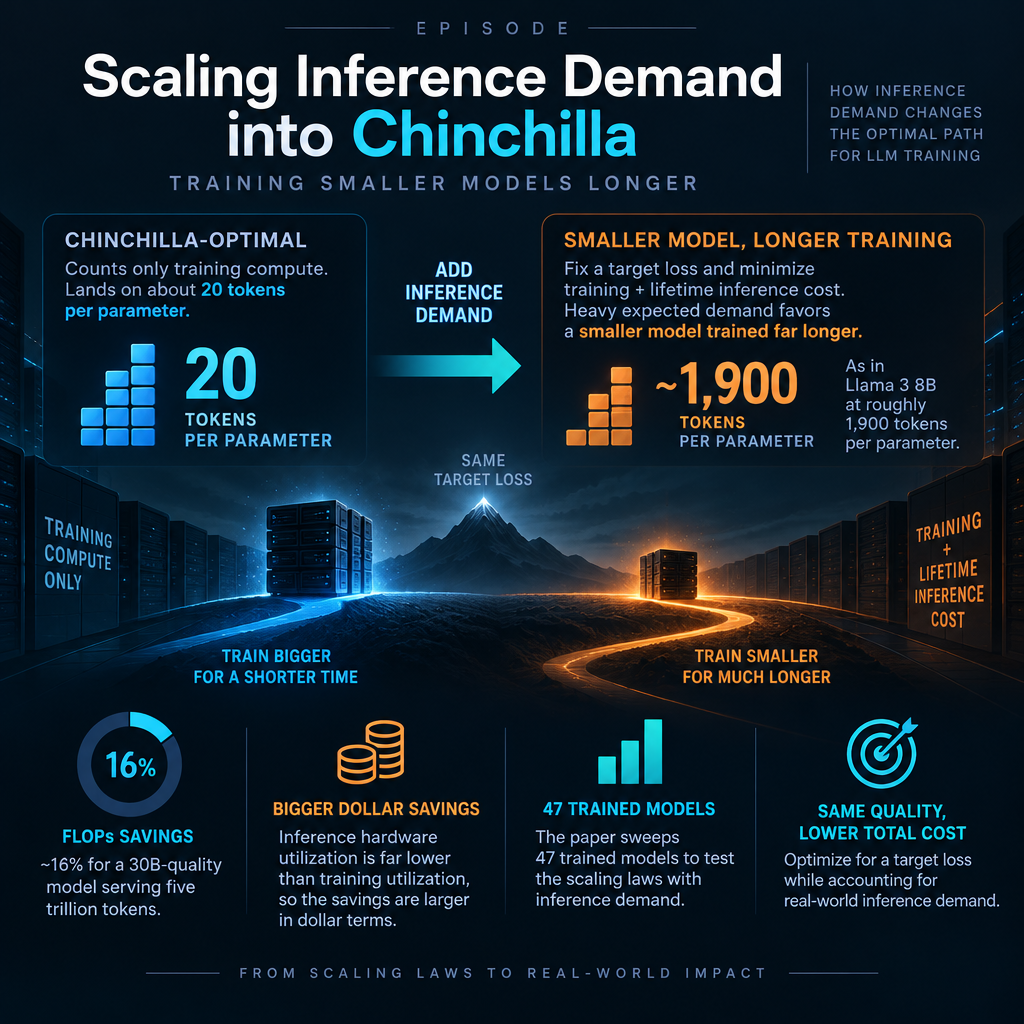
This episode examines "Beyond Chinchilla-Optimal," a paper from Databricks MosaicML that adds inference demand to LLM scaling laws. Chinchilla sizing counts only training compute, which is why it lands on about 20 tokens per parameter. The paper instead fixes a target loss and minimizes training plus lifetime inference cost. Heavy expected demand then favors a smaller model trained far longer, as in Llama 3 8B at roughly 1,900 tokens per parameter. The discussion covers the numerical solution and the FLOPs-only savings, such as about 16% for a 30B-quality model serving five trillion tokens. It then moves to dollar costs, where inference hardware utilization is far lower than training utilization, so the savings are larger. It also covers the paper's sweep of 47 trained models, which tests whether small models keep improving at extreme data ratios, and its refit of the Chinchilla coefficients. The hosts flag a weakness: the extreme end of the sweep rests mostly on one small model, while the recommendations are meant for much larger ones. Listeners get a clear explanation of why over-training can be economically rational, and a skeptical look at how well the evidence supports it.
Sources:
1. Scaling Inference Demand into Chinchilla: Training Smaller Models Longer
https://raw.githubusercontent.com/mlresearch/v235/main/assets/sardana24a/sardana24a.pdf
2. Training Compute-Optimal Large Language Models — Jordan Hoffmann, Sebastian Borgeaud, Arthur Mensch, et al. (DeepMind), 2022
https://scholar.google.com/scholar?q=Training+Compute-Optimal+Large+Language+Models
3. Scaling Laws for Neural Language Models — Jared Kaplan, Sam McCandlish, Tom Henighan, et al. (OpenAI), 2020
https://scholar.google.com/scholar?q=Scaling+Laws+for+Neural+Language+Models
4. LLaMA: Open and Efficient Foundation Language Models — Hugo Touvron, Thibaut Lavril, Gautier Izacard, et al. (Meta AI), 2023
https://scholar.google.com/scholar?q=LLaMA%3A+Open+and+Efficient+Foundation+Language+Models
5. Scaling Data-Constrained Language Models — Niklas Muennighoff, Alexander Rush, Boaz Barak, et al., 2023
https://scholar.google.com/scholar?q=Scaling+Data-Constrained+Language+Models
6. Llama 2: Open Foundation and Fine-Tuned Chat Models / The Llama 3 Herd of Models — Hugo Touvron et al.; Llama Team, AI@Meta, 2023 / 2024
https://scholar.google.com/scholar?q=Llama+2%3A+Open+Foundation+and+Fine-Tuned+Chat+Models+%2F+The+Llama+3+Herd+of+Models
7. Scaling Laws for Precision — Tanishq Kumar, Zachary Ankner, Benjamin Spector, et al., 2024
https://scholar.google.com/scholar?q=Scaling+Laws+for+Precision
8. Resolving Discrepancies in Compute-Optimal Scaling of Language Models — Tomer Porian, Mitchell Wortsman, Jenia Jitsev, Ludwig Schmidt, Yair Carmon, 2024
https://scholar.google.com/scholar?q=Resolving+Discrepancies+in+Compute-Optimal+Scaling+of+Language+Models
9. Efficiently Scaling Transformer Inference — Reiner Pope, Sholto Douglas, Aakanksha Chowdhery, Jacob Devlin, James Bradbury, et al…


