

Shownotes
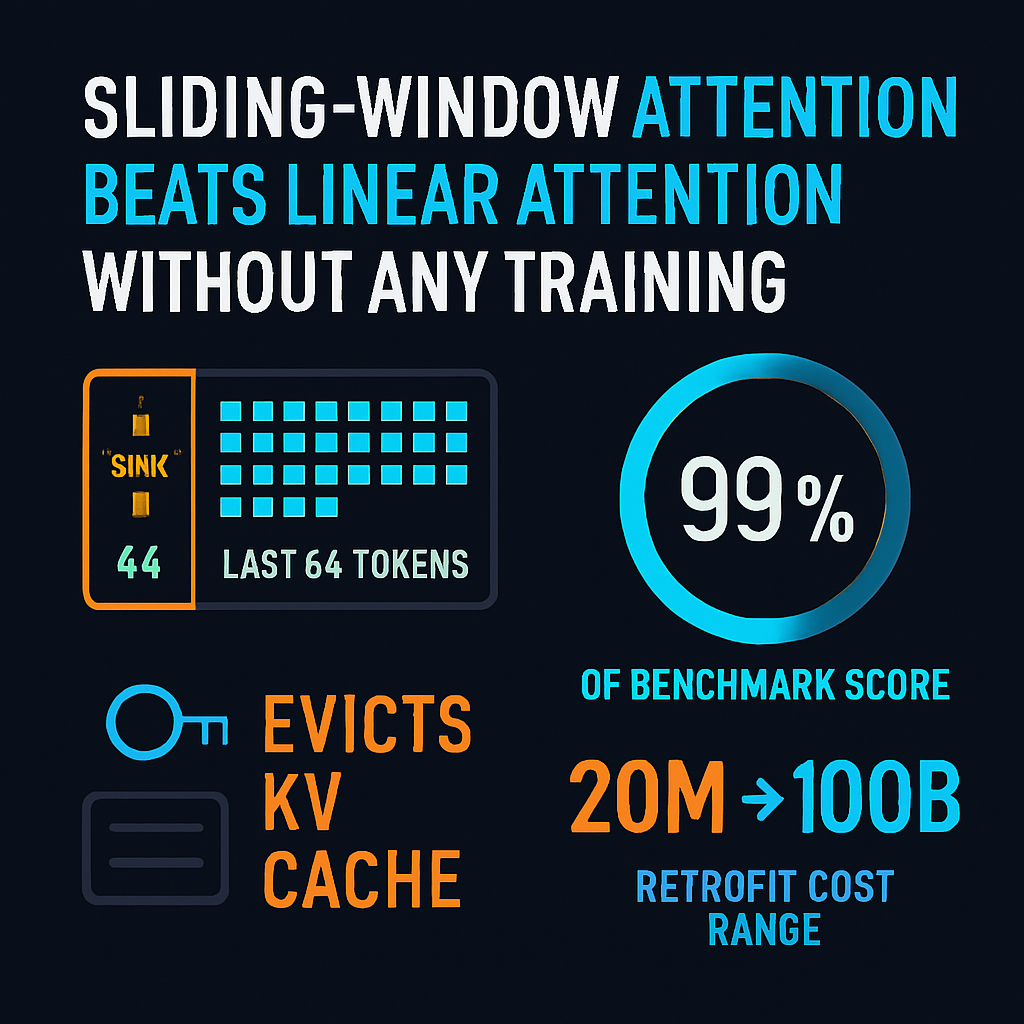
This episode examines a paper claiming that a pretrained LLM can be cut down to a sliding window of the last 64 tokens plus four "attention sink" starting tokens, with no training, and still keep about 99% of its benchmark score. That result would match months of work on retrofitting models into linear attention. The discussion builds up the background: the KV cache and how eviction differs from fixed-size linear-attention state, why StreamingLLM's sinks keep windowing from collapsing, and how retrofit costs range from roughly 20 million to 100 billion training tokens. It then questions what "99% recovery" means, noting that log-likelihood multiple-choice benchmarks like MMLU and HellaSwag mostly need only nearby context, unlike generative tasks such as GSM8K and HumanEval. It also asks whether the comparison is fair when memory budgets aren't held equal. Listeners get a skeptical look at whether a simple free baseline is outperforming retrofit methods, or whether the benchmarks are just too local to tell.
Sources:
1. Sliding-window beats linear attention — Alexia Jolicoeur-Martineau, Rhea Sanjay Sukthanker, Pashmina Cameron, Emy Gervais, 2026
http://arxiv.org/abs/2608.28444
2. Efficient Streaming Language Models with Attention Sinks — Guangxuan Xiao, Yuandong Tian, Beidi Chen, Song Han, Mike Lewis, 2023 (ICLR 2024)
https://scholar.google.com/scholar?q=Efficient+Streaming+Language+Models+with+Attention+Sinks
3. Longformer: The Long-Document Transformer — Iz Beltagy, Matthew E. Peters, Arman Cohan, 2020
https://scholar.google.com/scholar?q=Longformer%3A+The+Long-Document+Transformer
4. Mistral 7B — Albert Q. Jiang et al. (Mistral AI), 2023
https://scholar.google.com/scholar?q=Mistral+7B
5. Gemma 2: Improving Open Language Models at a Practical Size (and Gemma 3 Technical Report) — Gemma Team, Google DeepMind, 2024 / 2025
https://scholar.google.com/scholar?q=Gemma+2%3A+Improving+Open+Language+Models+at+a+Practical+Size+%28and+Gemma+3+Technical+Report%29
6. Transformers are RNNs: Fast Autoregressive Transformers with Linear Attention — Angelos Katharopoulos, Apoorv Vyas, Nikolaos Pappas, François Fleuret, 2020
https://scholar.google.com/scholar?q=Transformers+are+RNNs%3A+Fast+Autoregressive+Transformers+with+Linear+Attention
7. Finetuning Pretrained Transformers into RNNs — Jungo Kasai, Hao Peng, Yizhe Zhang, Dani Yogatama, Gabriel Ilharco, Nikolaos Pappas, Yi Mao, Weizhu Chen, Noah A. Smith, 2021
https://scholar.google.com/scholar?q=Finetuning+Pretrained+Transformers+into+RNNs
8. LoLCATs: On Low-Rank Linearizing of Large Language Models — Michael Zhang, Simran Arora, Rahul Chalamala, Alan Wu, Benjamin Spector, Aaryan Singhal, Krithik Ramesh, Christopher Ré, 2024 (ICLR 2025)
https://scholar.google.com/scholar?q=LoLCATs%3A+On+Low-Rank+Linearizing+of+Large+Language+Models
9. Transformers to SSMs: Distilling Quadratic Knowledge to Subquadratic Models (MOHAWK) — Aviv Bick, Kevin Y. Li, Eric P. Xing, J. Zico Kolter, Albert Gu…

