
RewardAnything: Generalizable Principle-Following Reward Models
· 21 min · Temporada 3 Episódio 10
Notas do episódio
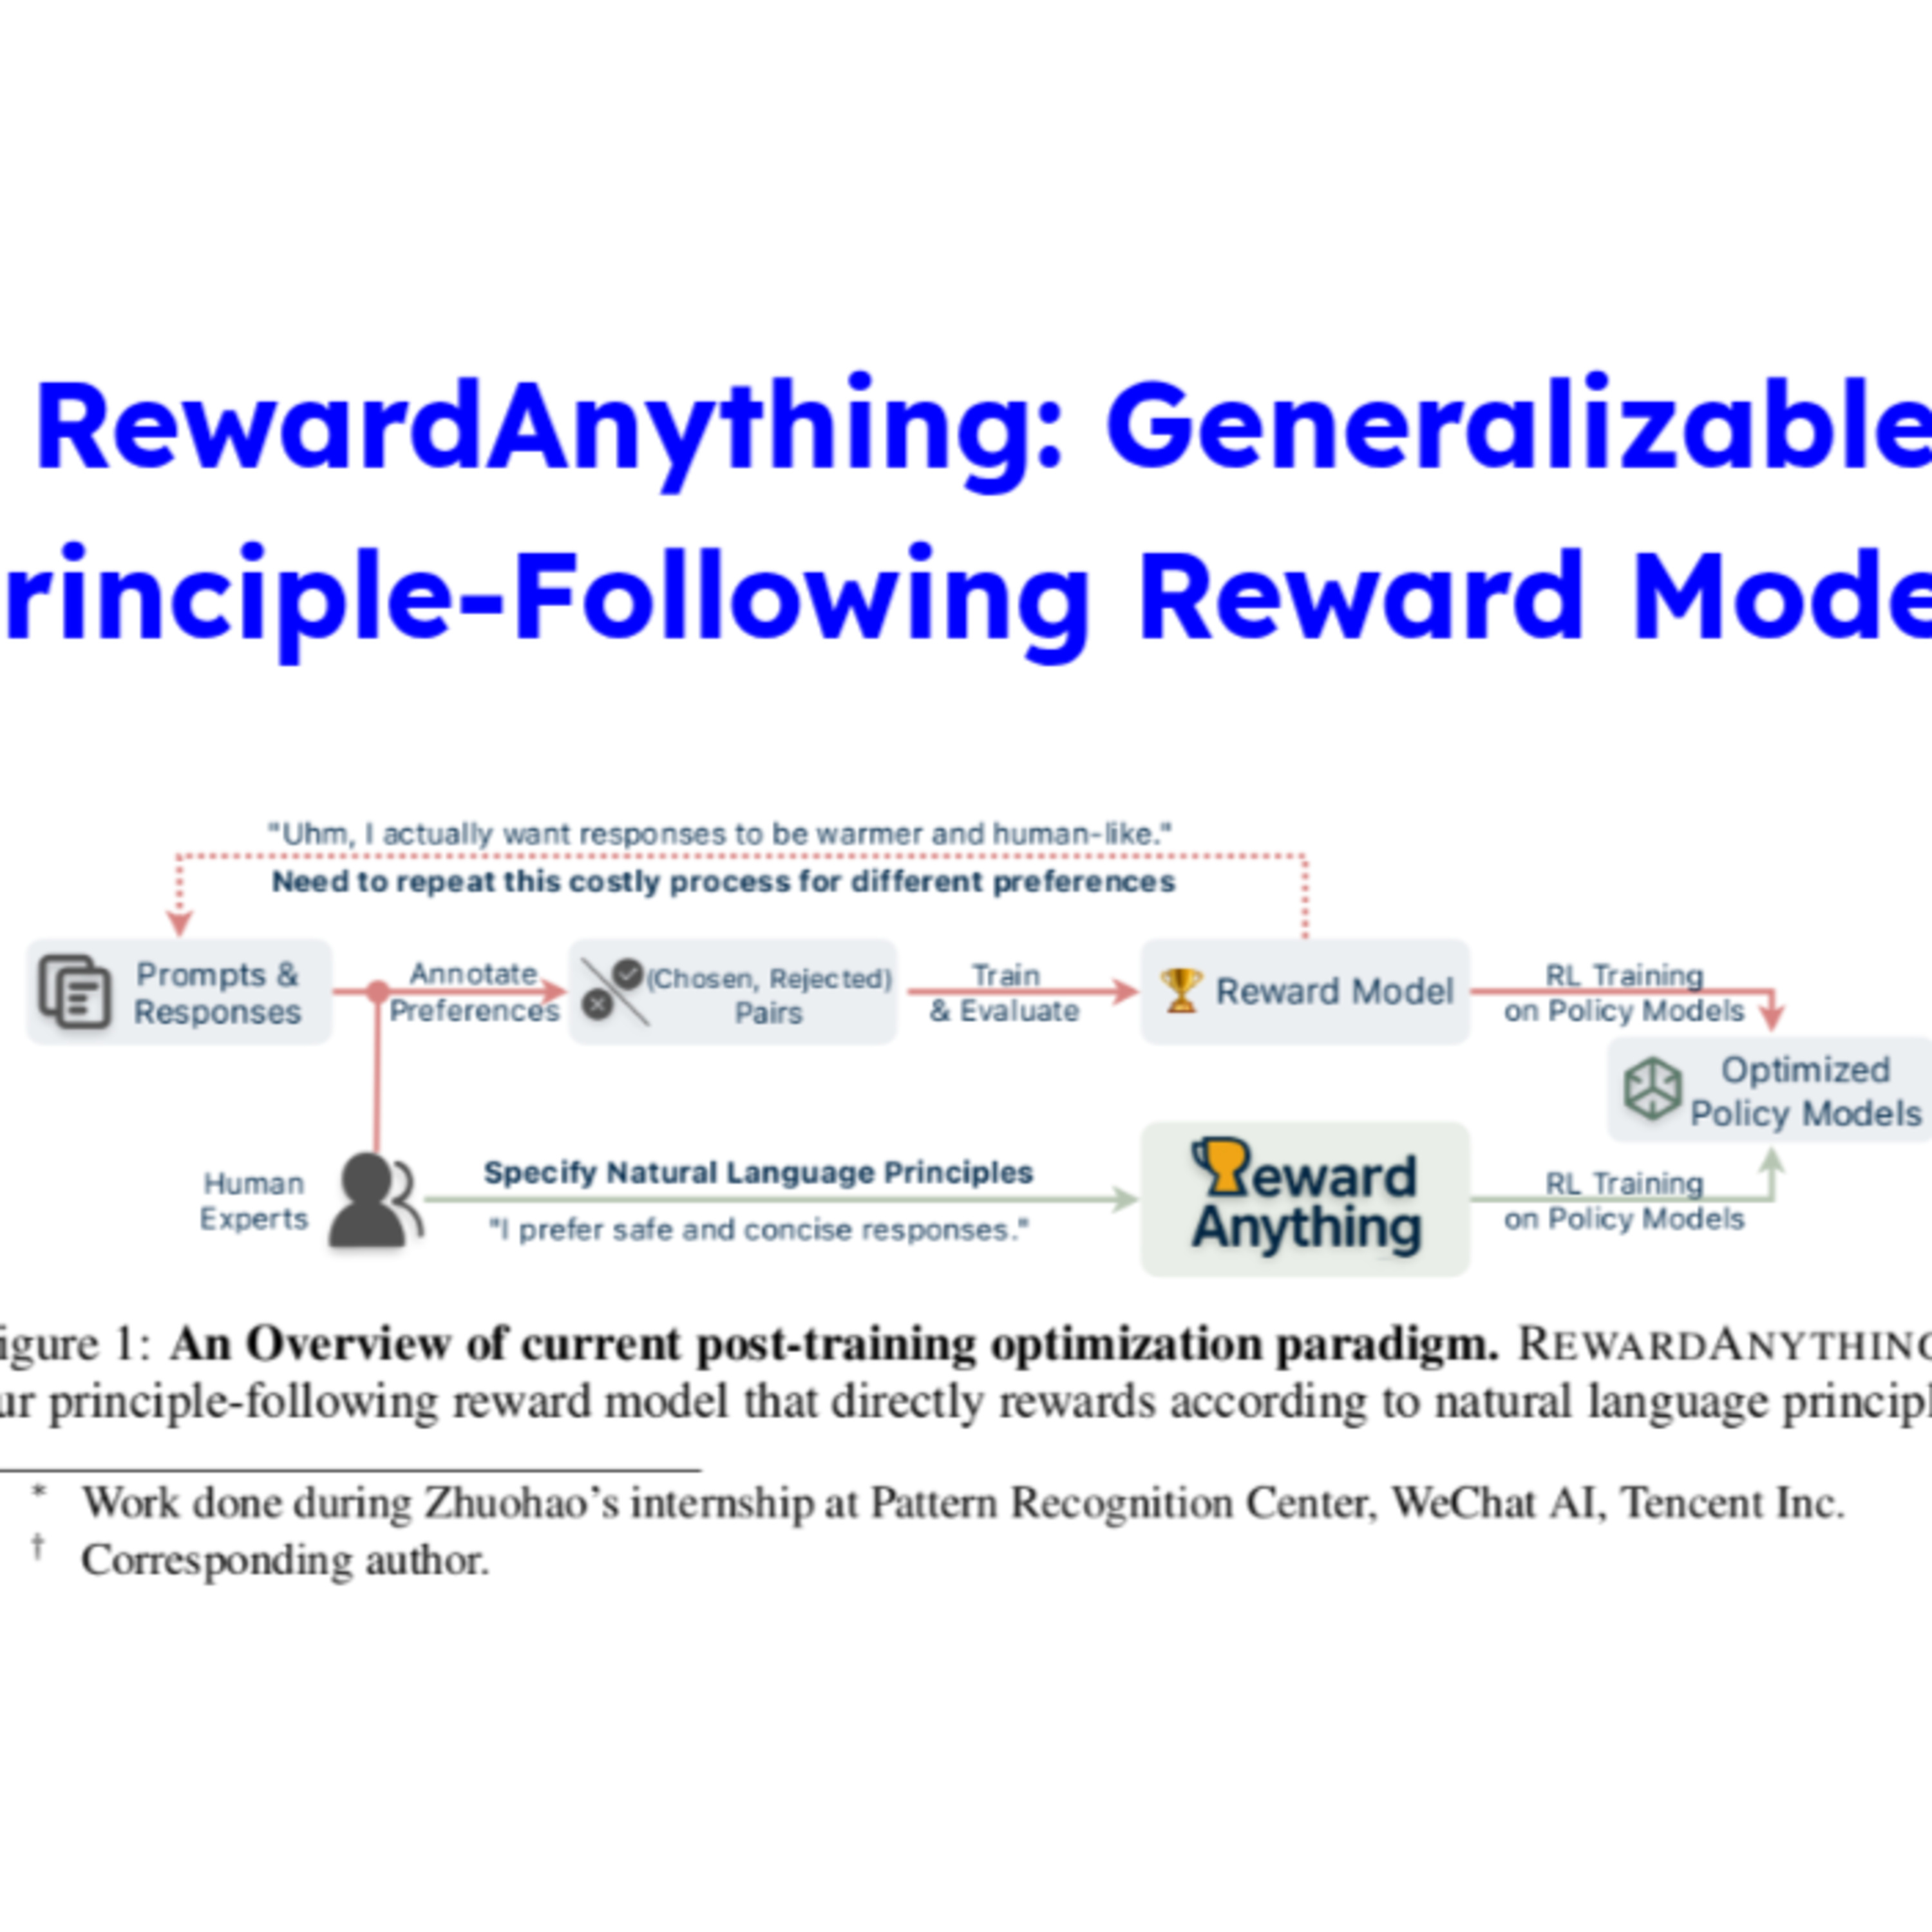
What if the biggest barrier to truly aligned AI wasn't a lack of data, but a failure of language? We spend millions on retraining LLMs for every new preference—from a customer service bot that must be concise to a research assistant that must be exhaustive. This is fundamentally broken.
Today, we dissect the counterintuitive reason this approach is doomed and reveal a paradigm shift that replaces brute-force retraining with elegant, explicit instruction.
This episode is a deep dive into the blueprint behind "Reward Anything," a groundbreaking reward model architecture from Peking University…
Site: podcasters.spotify.com


