
The Great Undertraining: How a 70B Model Called Chinchilla Exposed the AI Industry's Billion-Dollar Mistake
· 14 min · Saison 3 Épisode 11
Notes d’épisode
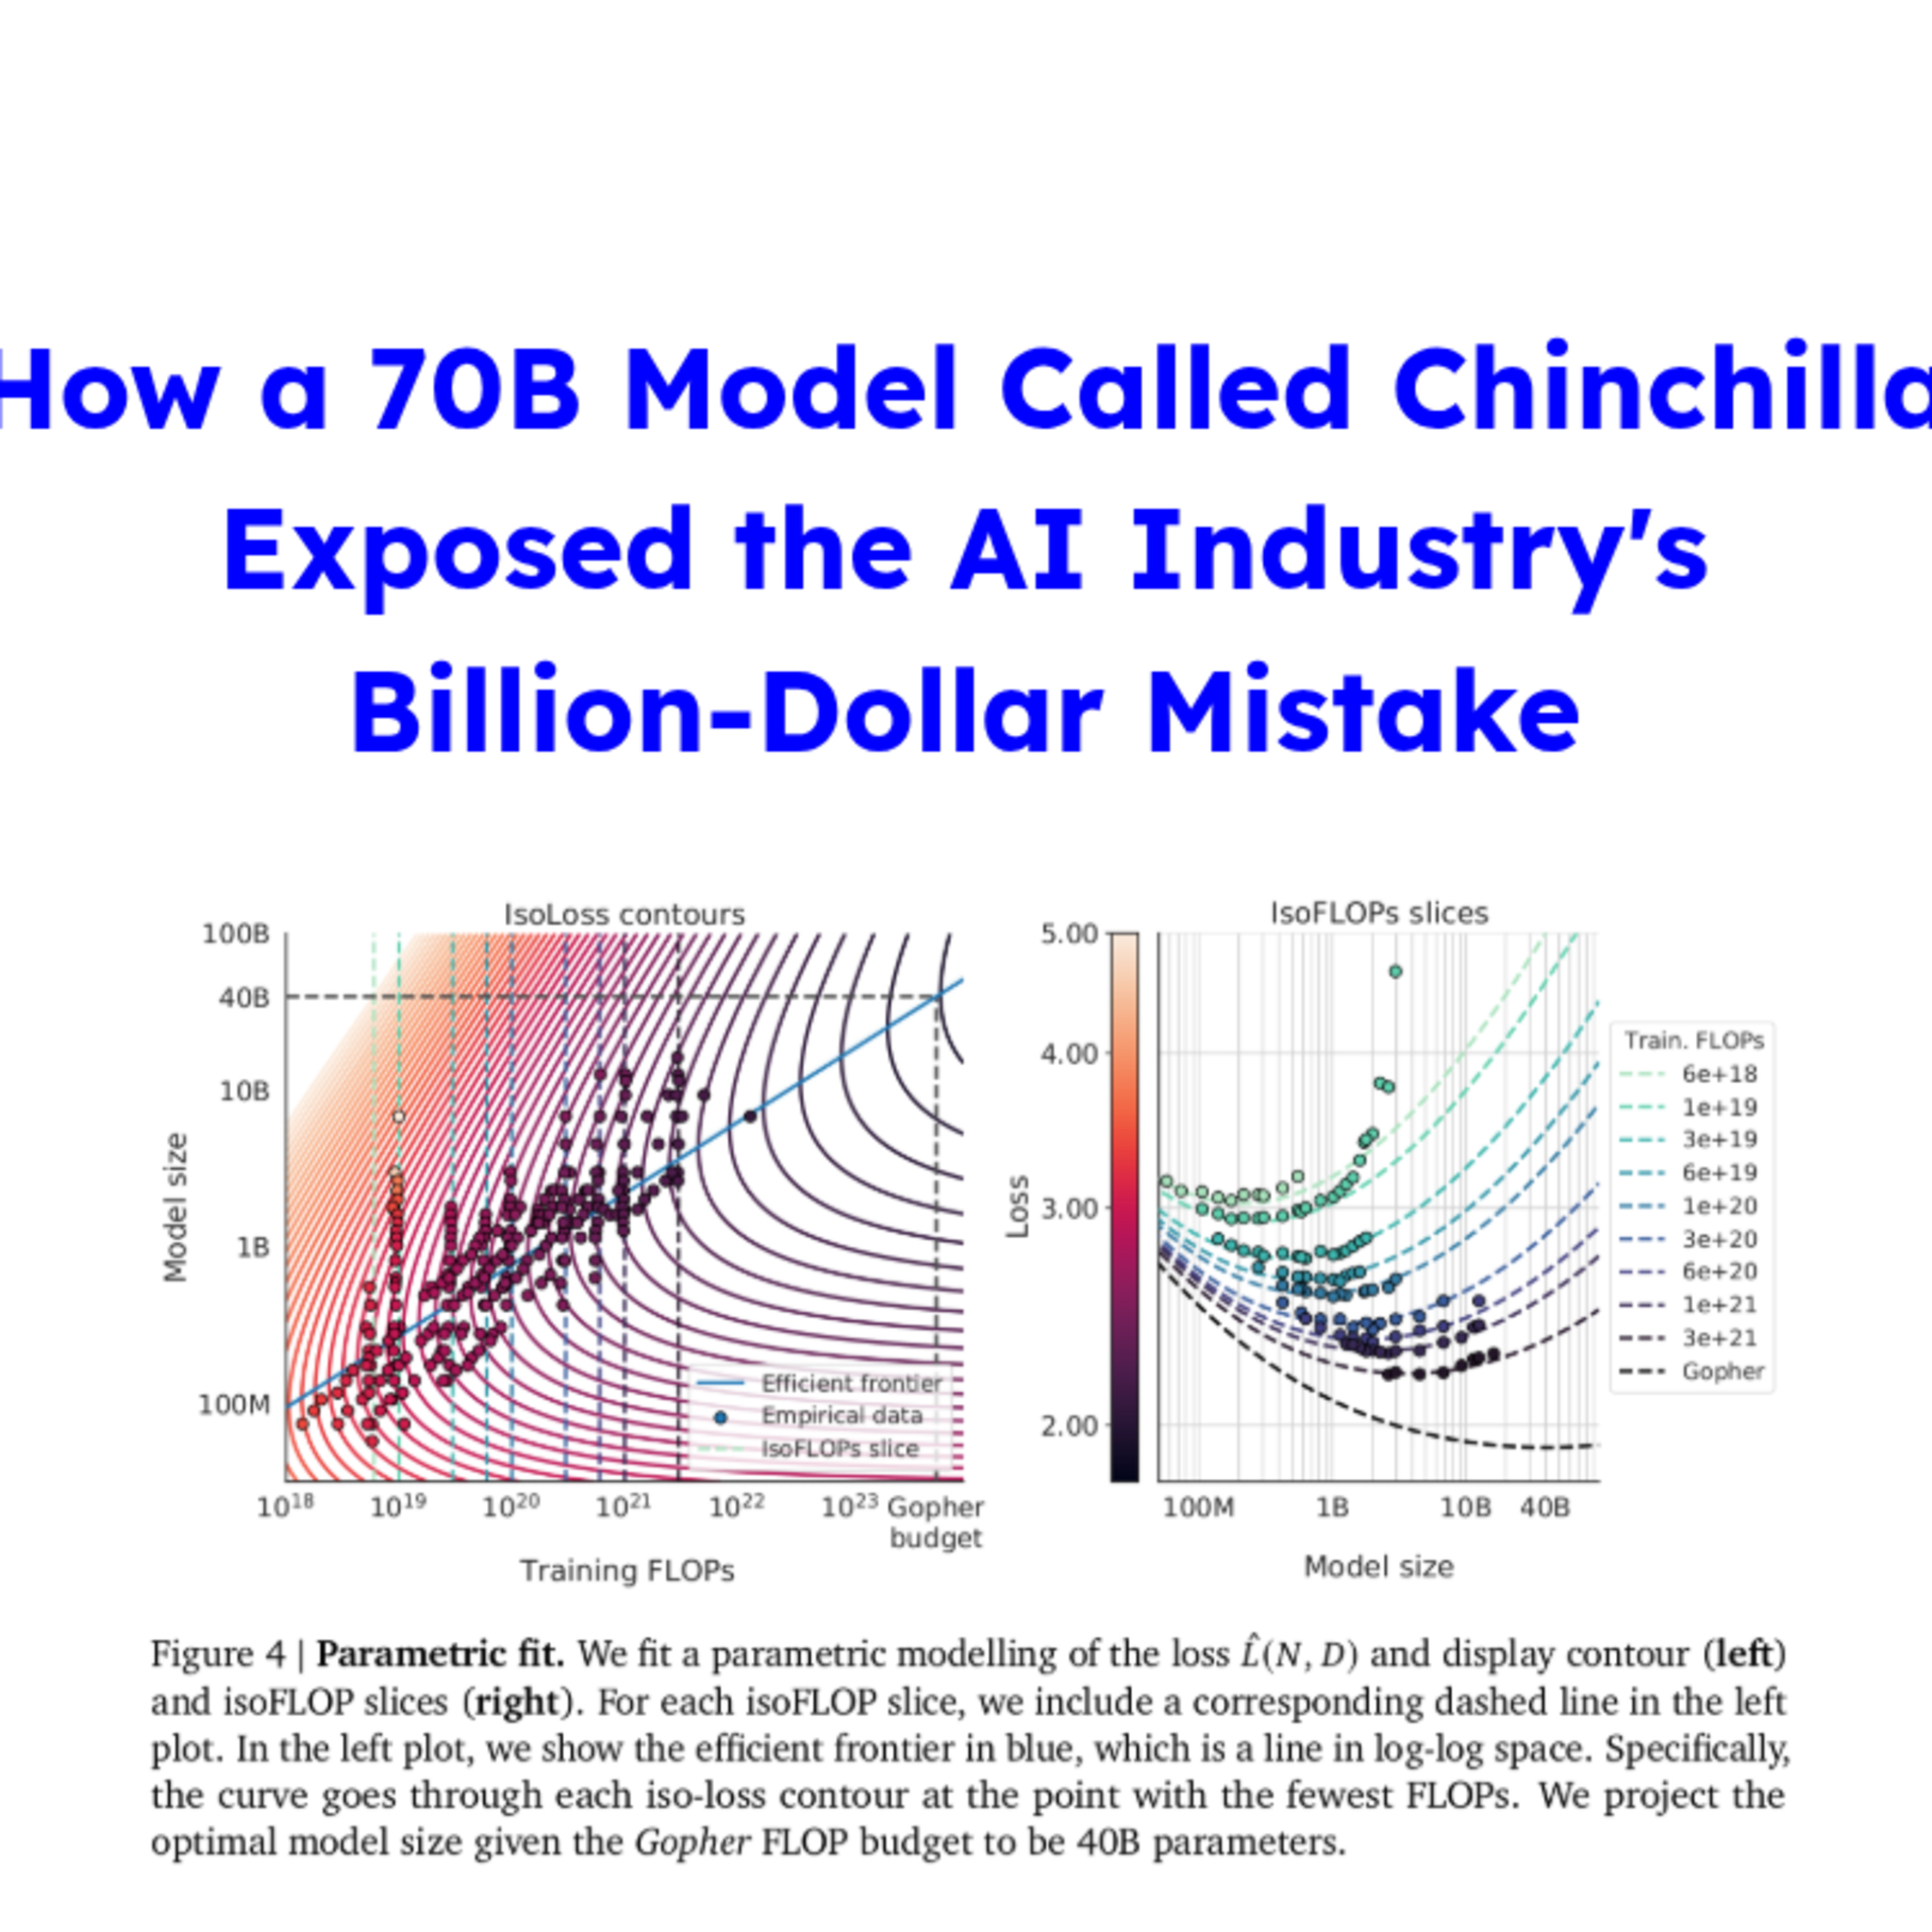
For years, a simple mantra has cost the AI industry billions: bigger is always better. The race to scale models to hundreds of billions of parameters—from GPT-3 to Gopher—seemed like a straight line to superior intelligence. But this assumption contains a profound and expensive flaw.
This episode reveals the non-obvious truth: many of the world's most powerful LLMs are profoundly undertrained, wasting staggering amounts of compute on a suboptimal architecture. We dissect the groundbreaking research that proves it, revealing a new, radically more efficient path forward.
Enter Chinchilla, a…
Site web: podcasters.spotify.com


