

Poznámky k epizodě
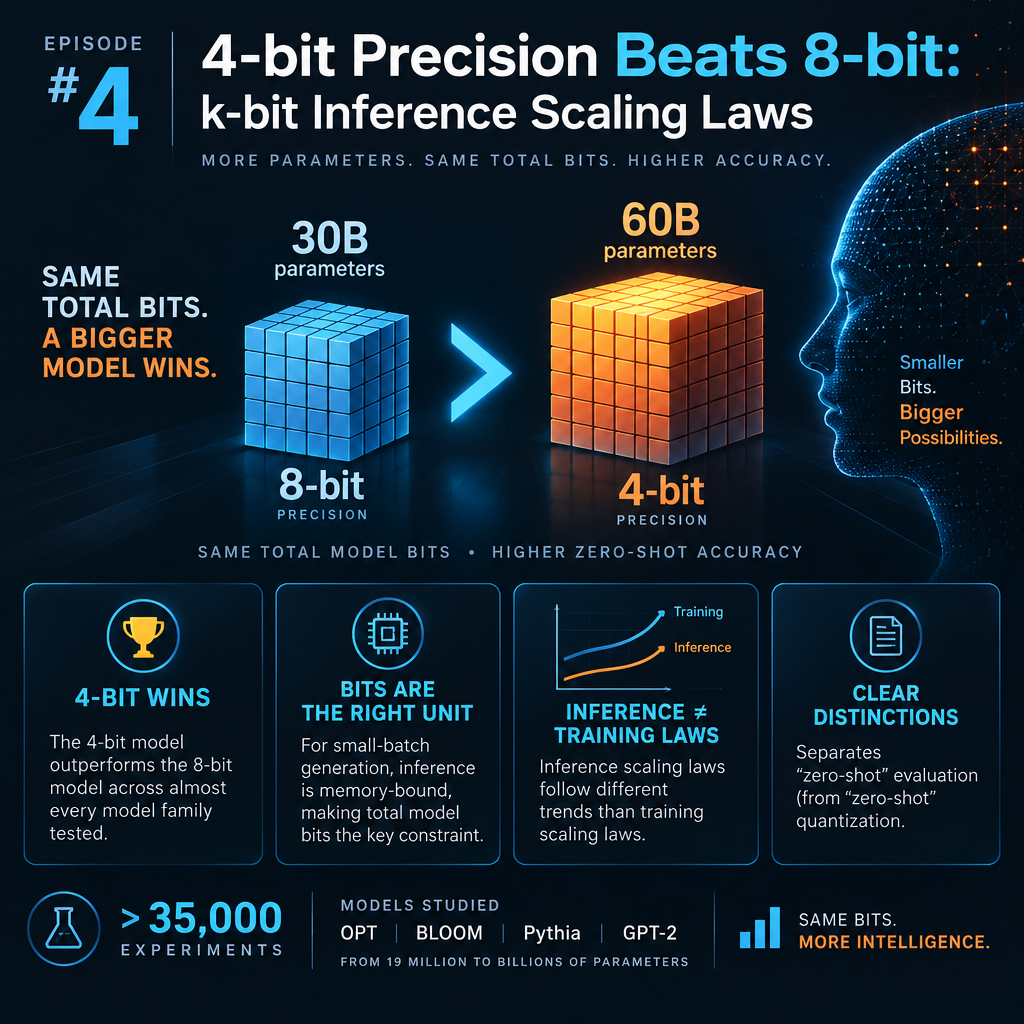
This episode examines the paper "The case for 4-bit precision: k-bit Inference Scaling Laws," which asks, for a fixed total number of model bits, which weight precision gives the best zero-shot accuracy. It opens with a puzzle: a 30-billion-parameter model stored in 8 bits versus a 60-billion-parameter model stored in 4 bits. The paper finds the 4-bit model wins across almost every family tested. The discussion builds the background step by step. It covers why bits are the right unit when small-batch generation is memory-bound, and how inference scaling laws differ from training laws. It also separates "zero-shot" evaluation from "zero-shot" quantization. The episode then walks through the knobs studied across more than 35,000 experiments on OPT, BLOOM, Pythia and GPT-2 models from 19 million to 176 billion parameters. Those knobs are block-wise normalization, data types such as integer, float, quantile and dynamic exponent, and a proxy-based method that keeps outlier dimensions in 16-bit. Listeners get a clear explanation of the trade-offs, along with a skeptical look at how far "4-bit is optimal" reaches given the specific methods and bit accounting used.
Sources:
1. 4-bit Precision Beats 8-bit: k-bit Inference Scaling Laws
https://arxiv.org/pdf/2212.09720
2. Language Models are Unsupervised Multitask Learners — Alec Radford, Jeffrey Wu, Rewon Child, David Luan, Dario Amodei, Ilya Sutskever, 2019
https://scholar.google.com/scholar?q=Language+Models+are+Unsupervised+Multitask+Learners
3. Language Models are Few-Shot Learners — Tom B. Brown et al. (OpenAI), 2020
https://scholar.google.com/scholar?q=Language+Models+are+Few-Shot+Learners
4. Scaling Laws for Neural Language Models — Jared Kaplan, Sam McCandlish, Tom Henighan, et al., 2020
https://scholar.google.com/scholar?q=Scaling+Laws+for+Neural+Language+Models
5. LLM.int8(): 8-bit Matrix Multiplication for Transformers at Scale — Tim Dettmers, Mike Lewis, Younes Belkada, Luke Zettlemoyer, 2022
https://scholar.google.com/scholar?q=LLM.int8%28%29%3A+8-bit+Matrix+Multiplication+for+Transformers+at+Scale
6. Zero-Shot Learning with Semantic Output Codes / Learning to Detect Unseen Object Classes by Between-Class Attribute Transfer — Mark Palatucci et al. (2009); Christoph Lampert, Hannes Nickisch, Stefan Harmeling (2009), 2009
https://scholar.google.com/scholar?q=Zero-Shot+Learning+with+Semantic+Output+Codes+%2F+Learning+to+Detect+Unseen+Object+Classes+by+Between-Class+Attribute+Transfer
7. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers — Frantar, Ashkboos, Hoefler, Alistarh, 2022
https://scholar.google.com/scholar?q=GPTQ%3A+Accurate+Post-Training+Quantization+for+Generative+Pre-trained+Transformers
8. AWQ: Activation-aware Weight Quantization for LLM Compression and Acceleration — Lin, Tang, Tang, Yang, Dang, Han, 2023
https://scholar.google.com/scholar?q=AWQ%3A+Activation-aware+Weight+Quantization+for+LLM+Compression+and+Acceleration
9. SmoothQuant: Accurate…


