

Notes d’épisode
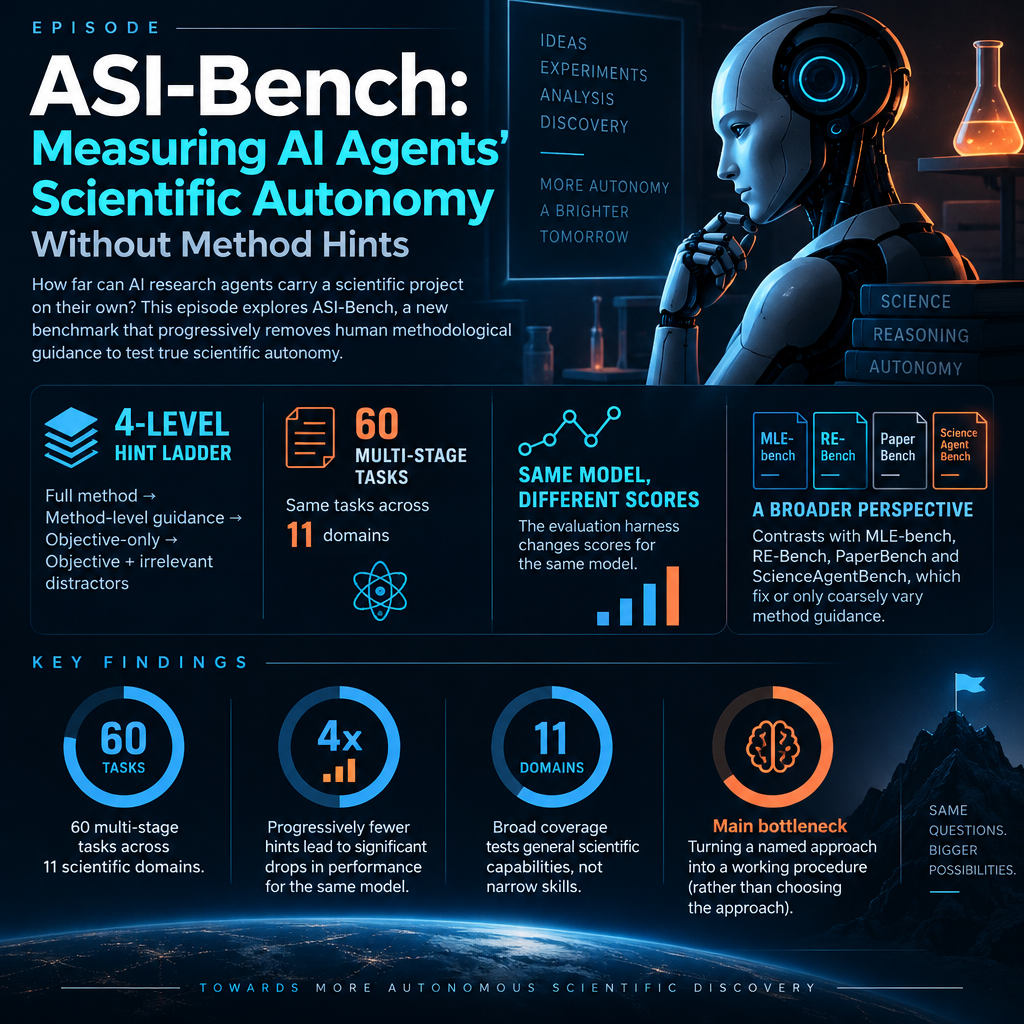
This episode examines ASI-Bench, a benchmark that tests how far AI research agents can carry a scientific project on their own as human methodological guidance is progressively removed. It covers the four-level "hint ladder" (full method, method-level guidance, objective-only, and objective plus irrelevant distractors) applied to the same 60 multi-stage tasks across 11 domains. Agent-and-model pairs are evaluated, and the harness is shown to change scores for the same model. It contrasts this design with MLE-bench, RE-Bench, PaperBench and ScienceAgentBench, which fix or only coarsely vary how much method the agent is given. The discussion centers on the authors' claim that turning a named approach into a working procedure, rather than choosing the approach, is the main bottleneck. It also weighs a competing reading: the score drop when hints disappear may partly reflect lost information such as exact equations and constants, not just a failure of operationalization. Listeners get a skeptical look at what the benchmark's construction (over 40 experts, 31,000 human hours, leakage checks) can and cannot establish about agent autonomy.
Sources:
1. ASI-Bench: At the Dawn of Artificial Superintelligence — Junwei Zhou, Zhen Sun, Binyu Li, Jiangyu Zhou, Yuexi Pan, Hengyu Wang, Honghe Ren, Xiaohan Jia, Xueyang Zhou, Xiaoyu Cao, Yongchao Chen, Yuanning Feng, Junhao Wu, Cheng Zhang, Sijia Chen, Haoyu Xue, Chengsong You, Huan Wang, Koutian Wu, Peigan Gao, Jiakun Wu, Wenzhe Li, Ergan Shang, Qingyuan Zheng, Jingjing Zhou, Ruixuan Jia, Yan Xu, Hongrui Zhang, Xiao-Han Ma, Zhengxiang Cheng, Yuexing Hao, Liting Mai, Xianglin Ji, Wenjun Zhang, Zhuofan Chen, Yixiao Huang, Chi Wang, Wenyue Hua, Yilun Hao, Yuantao Zhai, Ziyan Zhao, Jingyan Xie, 2026
http://arxiv.org/abs/2608.17271
2. ASI-Bench: At the Dawn of Artificial Superintelligence — Junwei Zhou, Zhen Sun, et al.; corresponding author Yongchao Chen (Tsinghua University and collaborators), 2026
https://scholar.google.com/scholar?q=ASI-Bench%3A+At+the+Dawn+of+Artificial+Superintelligence
3. PaperBench: Evaluating AI's Ability to Replicate AI Research — Giulio Starace, Oliver Jaffe, et al. (OpenAI), 2025
https://scholar.google.com/scholar?q=PaperBench%3A+Evaluating+AI%27s+Ability+to+Replicate+AI+Research
4. MLE-bench: Evaluating Machine Learning Agents on Machine Learning Engineering — Jun Shern Chan, Neil Chowdhury, et al. (OpenAI), 2024
https://scholar.google.com/scholar?q=MLE-bench%3A+Evaluating+Machine+Learning+Agents+on+Machine+Learning+Engineering
5. SWE-bench: Can Language Models Resolve Real-World GitHub Issues? — Carlos E. Jimenez, John Yang, et al. (Princeton), 2023
https://scholar.google.com/scholar?q=SWE-bench%3A+Can+Language+Models+Resolve+Real-World+GitHub+Issues%3F
6. ScienceAgentBench: Toward Rigorous Assessment of Language Agents for Data-Driven Scientific Discovery — Ziru Chen et al…

