

Beschrijving
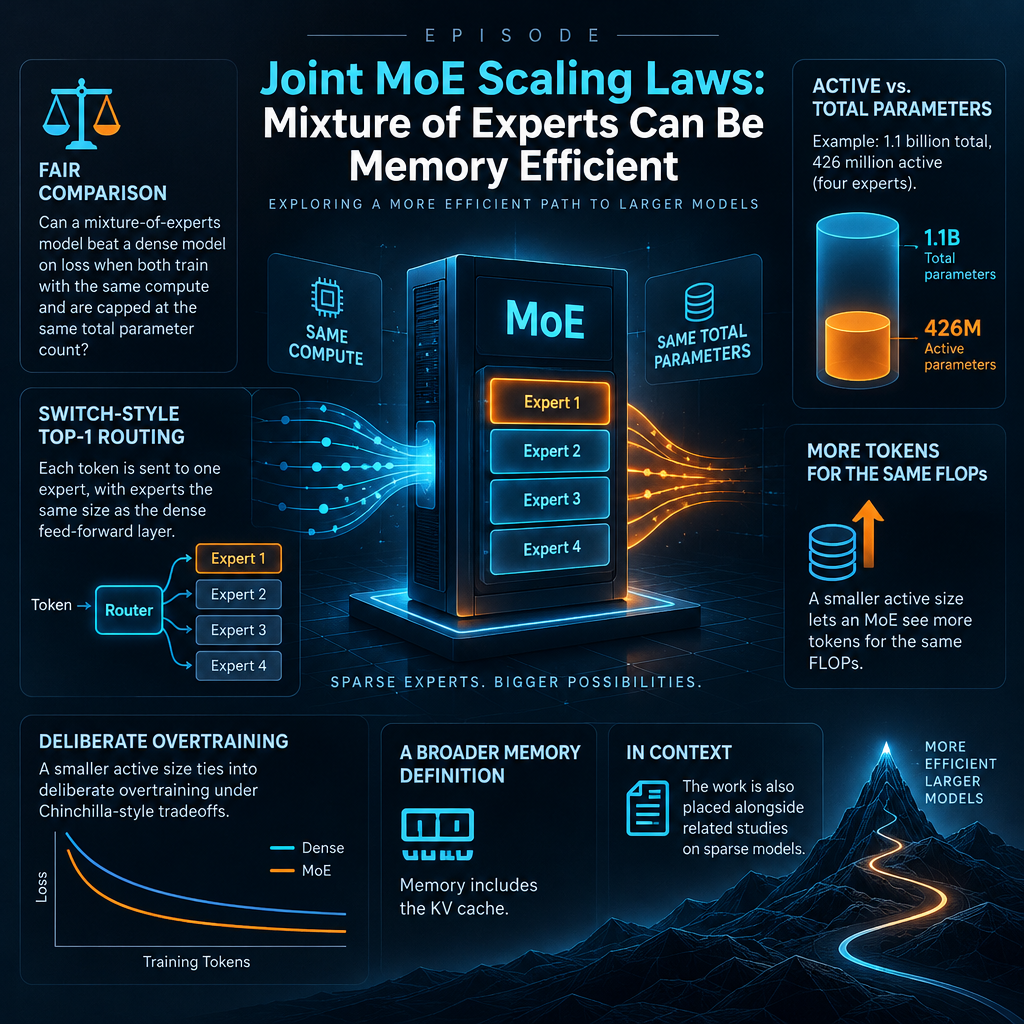
This episode explores the paper "Joint MoE Scaling Laws: Mixture of Experts Can Be Memory Efficient," which asks whether a mixture-of-experts model can beat a dense model on loss when both train with the same compute and are capped at the same total parameter count. It covers how Switch-style top-1 routing works with experts the same size as the dense feed-forward layer. It also covers the difference between active and total parameters, using a 1.1 billion total, 426 million active, four-expert example. The discussion explains how a smaller active size lets an MoE see more tokens for the same FLOPs. That ties into deliberate overtraining under Chinchilla-style tradeoffs, and into a memory definition that includes the KV cache. The hosts also place the work alongside related studies on sparsity, inference-aware scaling and hardware efficiency. They flag the gap between a loss-based claim and real serving hardware as the question to keep in mind.
Sources:
1. Joint MoE Scaling Laws: Mixture of Experts Can Be Memory Efficient
https://arxiv.org/pdf/2502.05172
2. Parameters vs FLOPs: Scaling Laws for Optimal Sparsity for Mixture-of-Experts Language Models — Samira Abnar, Harshay Shah, Dan Busbridge, et al., 2025
https://scholar.google.com/scholar?q=Parameters+vs+FLOPs%3A+Scaling+Laws+for+Optimal+Sparsity+for+Mixture-of-Experts+Language+Models
3. Toward Inference-Optimal Mixture-of-Expert Large Language Models — Longfei Yun, Yonghao Zhuang, Yao Fu, Eric P. Xing, Hao Zhang, 2024
https://scholar.google.com/scholar?q=Toward+Inference-Optimal+Mixture-of-Expert+Large+Language+Models
4. Beyond Chinchilla-Optimal: Accounting for Inference in Language Model Scaling Laws — Nikhil Sardana, Jacob Portes, Sasha Doubov, Jonathan Frankle, 2024
https://scholar.google.com/scholar?q=Beyond+Chinchilla-Optimal%3A+Accounting+for+Inference+in+Language+Model+Scaling+Laws
5. Unified Scaling Laws for Routed Language Models — Aidan Clark et al., 2022
https://scholar.google.com/scholar?q=Unified+Scaling+Laws+for+Routed+Language+Models
6. Scaling Laws for Fine-Grained Mixture of Experts — Jan Ludziejewski et al., 2024
https://scholar.google.com/scholar?q=Scaling+Laws+for+Fine-Grained+Mixture+of+Experts
7. Reconciling Kaplan and Chinchilla Scaling Laws / Resolving Discrepancies in Compute-Optimal Scaling of Language Models — Tomer Porian et al.; Tim Pearce & Jinyeop Song, 2024-2025
https://scholar.google.com/scholar?q=Reconciling+Kaplan+and+Chinchilla+Scaling+Laws+%2F+Resolving+Discrepancies+in+Compute-Optimal+Scaling+of+Language+Models
8. Scaling Laws and Compute-Optimal Training Beyond Fixed Training Durations — Alexander Hägele et al., 2024
https://scholar.google.com/scholar?q=Scaling+Laws+and+Compute-Optimal+Training+Beyond+Fixed+Training+Durations
9. OLMoE: Open Mixture-of-Experts Language Models — Niklas Muennighoff et al., 2024
https://scholar.google.com/scholar?q=OLMoE%3A+Open+Mixture-of-Experts+Language+Models
10. Fast Inference of Mixture-of-Experts Language Models…


