

Catatan episode
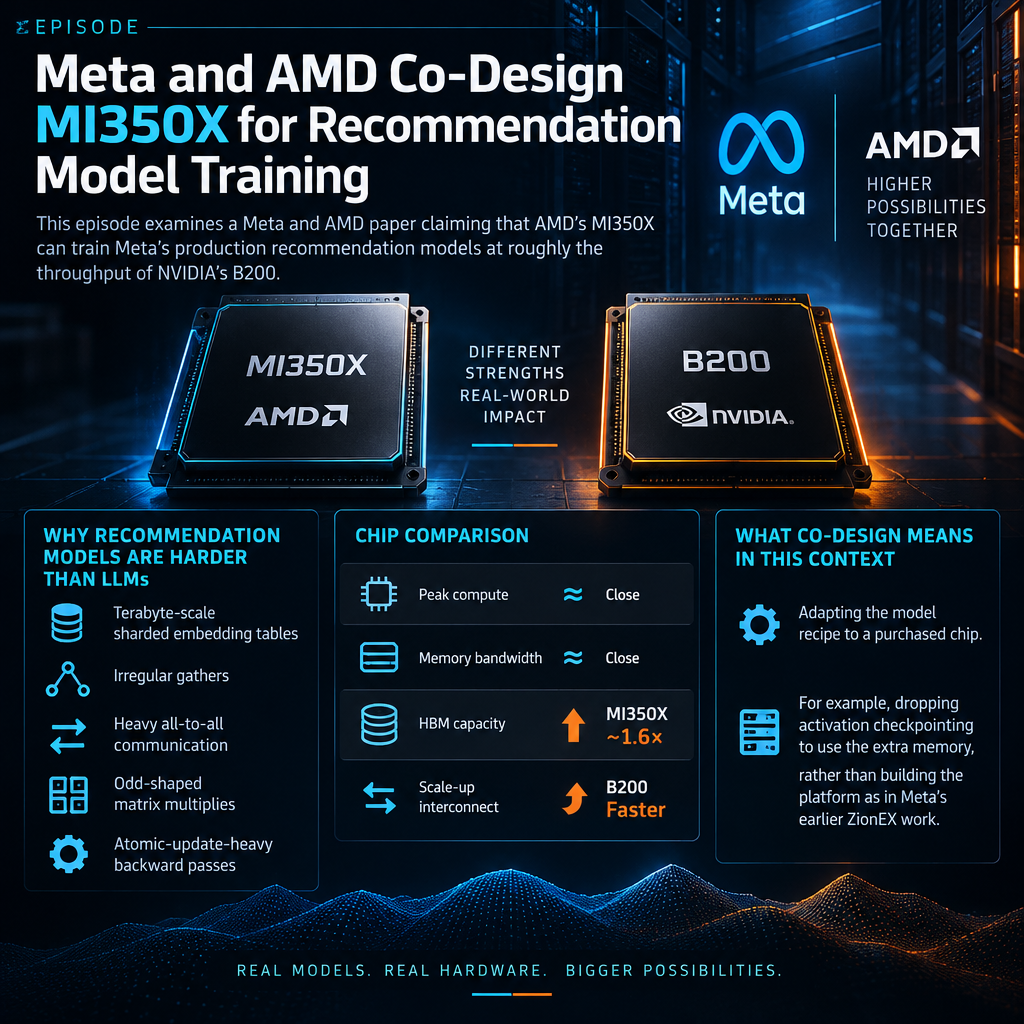
This episode examines a Meta and AMD paper claiming that AMD's MI350X can train Meta's production recommendation models at roughly the throughput of NVIDIA's B200. It explains why recommendation models are a harder training target than LLMs: terabyte-scale sharded embedding tables, irregular gathers, heavy all-to-all communication, odd-shaped matrix multiplies, and atomic-update-heavy backward passes. It compares the two chips. Peak compute and memory bandwidth are close, the MI350X has about 1.6 times the HBM capacity, and the B200 has faster scale-up interconnect. The discussion defines "co-design" as adapting the model recipe to a purchased chip, for example by dropping activation checkpointing to use the extra memory, rather than building the platform as in Meta's earlier ZionEX work. It also raises fairness concerns about the headline parity: the recipe was changed for the AMD hardware, several co-authors are AMD engineers, and the MI350X ran at 1000 watts against the B200's 750-watt cap. The episode previews the paper's analytical GEMM tile-selection model and its agentic CUDA-to-AMD kernel porting.
Sources:
1. Architecting for Hardware Diversity: Meta's End-to-End Co-Design for High-Performance AI Training on AMD GPUs — Haoyu Zhang, Arshad Rahman, Adnan Aziz, Ajith Prabhudev, Amin Farmahini, Ben Rhoads, Benson Ma, Brian Shi, Cen Zhao, CK Luk, Dingming Wu, Emad El-Haraty, Eric Chen, Frank Li, Gary Huang, Gefei Zuo, Haoran Zhang, Hiwot Kassa, Hongyi Zeng, Jack Taylor, Jeremy Hadidjojo, John Donati, Jonathan Sheffield, Julio Machado Silva, Karthik Ganesan, Kent Russell, KR Kishore, Lei Tian, Liu Ke, Muhammad Osama, Peng Chen, Rakesh Hemnani, Ryan Swann, Saleel Kudchadker, Shankar Yanamandram, Shobhit Kanaujia, Shucai Xiao, Srinath Bayareddy, Srinivas Vaidyanathan, Sudharssun Subramanian, Supadchaya Puangpontip, Taylor Robie, Tianhao Huang, Tyler Hart, Viswesh Sankaran, Weijun Jiang, Wenkai Du, Xiaodong Wang, Xiaohu Guo, Yao Rong, Yinbin Ma, Yue Dong, Yuzhen Huang, Yvonne Liu, Zhan Shu, Dan Rabinovitsj, Ajit Mathews, Chunqiang Tang, 2026
http://arxiv.org/abs/2610.22230
2. FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness — Tri Dao, Daniel Y. Fu, Stefano Ermon, Atri Rudra, Christopher Ré, 2022
https://scholar.google.com/scholar?q=FlashAttention%3A+Fast+and+Memory-Efficient+Exact+Attention+with+IO-Awareness
3. Deep Learning Recommendation Model for Personalization and Recommendation Systems — Maxim Naumov, Dheevatsa Mudigere, et al. (Facebook AI), 2019
https://scholar.google.com/scholar?q=Deep+Learning+Recommendation+Model+for+Personalization+and+Recommendation+Systems
4. Software-Hardware Co-design for Fast and Scalable Training of Deep Learning Recommendation Models — Dheevatsa Mudigere, Yuchen Hao, Jianyu Huang, et al., 2022
https://scholar.google.com/scholar?q=Software-Hardware+Co-design+for+Fast+and+Scalable+Training+of+Deep+Learning+Recommendation+Models
5. DeepSeek-V3 Technical Report (and the follow-up…


