

Show notes
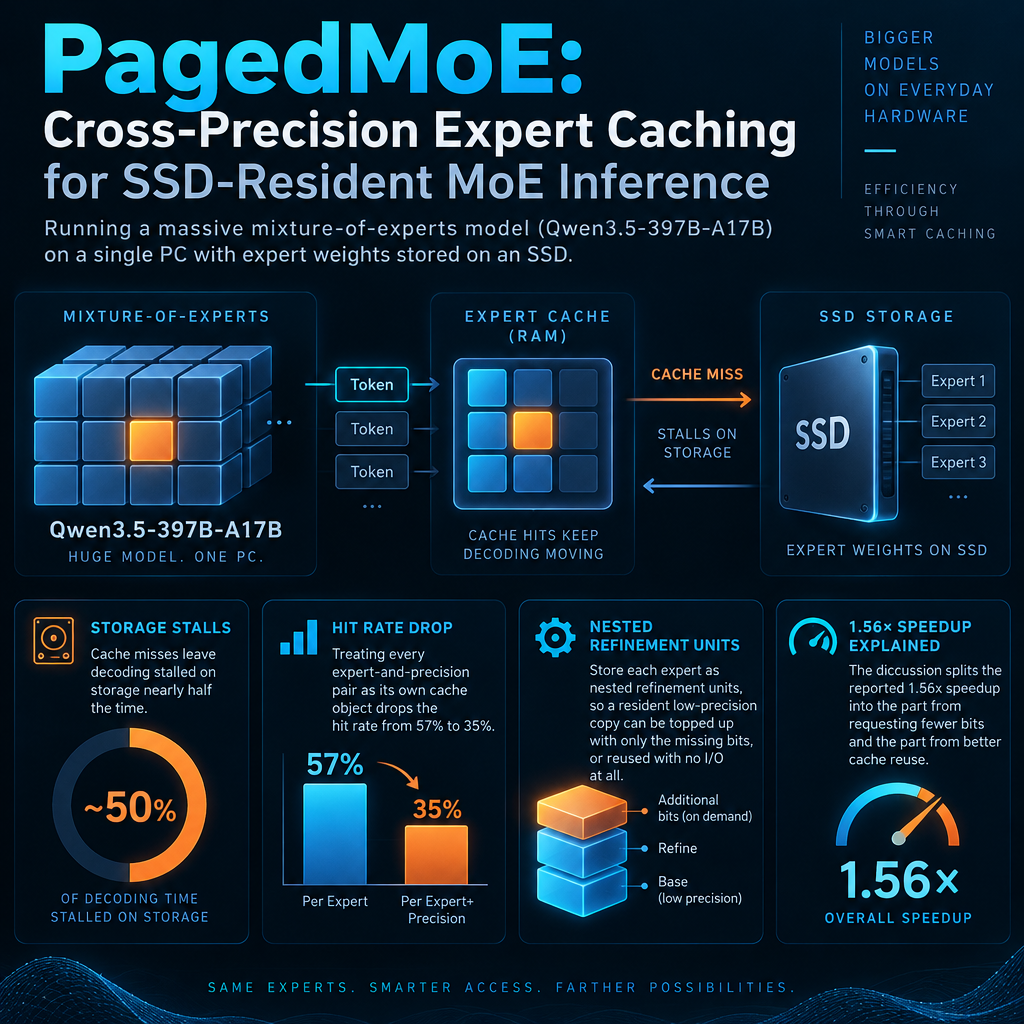
This episode examines PagedMoE, a system for running a huge mixture-of-experts model (Qwen3.5-397B-A17B) on a single PC with expert weights stored on an SSD. Cache misses leave decoding stalled on storage nearly half the time, and giving each token a different bit-width per expert would normally make that worse. Treating every expert-and-precision pair as its own cache object drops the hit rate from 57% to 35%. The paper's fix is to store each expert as nested refinement units, so a resident low-precision copy can be topped up with only the missing bits, or reused with no I/O at all. The discussion separates this idea from the prior work it borrows from (Matryoshka Quantization, Any-Precision LLM, SliceMoE, HOBBIT). It also splits the reported 1.56x speedup into the part from requesting fewer bits and the part from sharing cached bits across precisions. Listeners get a clear walk through the binary-tree codebook construction, the quantization-error numbers, and the limits of the evidence, such as a single-layer headroom study and no head-to-head comparison with SliceMoE.
Sources:
1. PagedMoE: Cross-Precision Expert Caching for Token-Level Dynamic Precision in SSD-Resident MoE Inference — Yutong Lin, Yingdi Shan, Shaoyuan Chen, Yuanyong Chen, Yongwei Wu, Mingxing Zhang, 2026
http://arxiv.org/abs/2611.03173
2. Fast Inference of Mixture-of-Experts Language Models with Offloading — Artyom Eliseev, Denis Mazur, 2023
https://scholar.google.com/scholar?q=Fast+Inference+of+Mixture-of-Experts+Language+Models+with+Offloading
3. MoE-Infinity: Efficient MoE Inference on Personal Machines with Sparsity-Aware Expert Cache — Leyang Xue, Yao Fu, Zhan Lu, Luo Mai, Mahesh Marina, 2024 (arXiv; later revisions)
https://scholar.google.com/scholar?q=MoE-Infinity%3A+Efficient+MoE+Inference+on+Personal+Machines+with+Sparsity-Aware+Expert+Cache
4. EdgeMoE: Empowering Sparse Large Language Models on Mobile Devices — Rongjie Yi, Liwei Guo, Shiyun Wei, Ao Zhou, Shangguang Wang, Mengwei Xu, 2023
https://scholar.google.com/scholar?q=EdgeMoE%3A+Empowering+Sparse+Large+Language+Models+on+Mobile+Devices
5. LLM in a Flash: Efficient Large Language Model Inference with Limited Memory — Keivan Alizadeh, Iman Mirzadeh, et al. (Apple), 2023
https://scholar.google.com/scholar?q=LLM+in+a+Flash%3A+Efficient+Large+Language+Model+Inference+with+Limited+Memory
6. HOBBIT: A Mixed Precision Expert Offloading System for Fast MoE Inference — Peng Tang, Jiacheng Liu, Xiaofeng Hou, et al., 2024
https://scholar.google.com/scholar?q=HOBBIT%3A+A+Mixed+Precision+Expert+Offloading+System+for+Fast+MoE+Inference
7. Mixture Compressor for Mixture-of-Experts LLMs Gains More (MC) — Wei Huang, Yue Liao, Jianhui Liu, et al., 2024
https://scholar.google.com/scholar?q=Mixture+Compressor+for+Mixture-of-Experts+LLMs+Gains+More+%28MC%29
8. GPTQ: Accurate Post-Training Quantization for Generative Pre-trained Transformers — Elias Frantar, Saleh Ashkboos, Torsten Hoefler, Dan Alistarh…

