
Demystifying Reinforcement Learning Post-Training of Language Models
· 20 min
Show notes
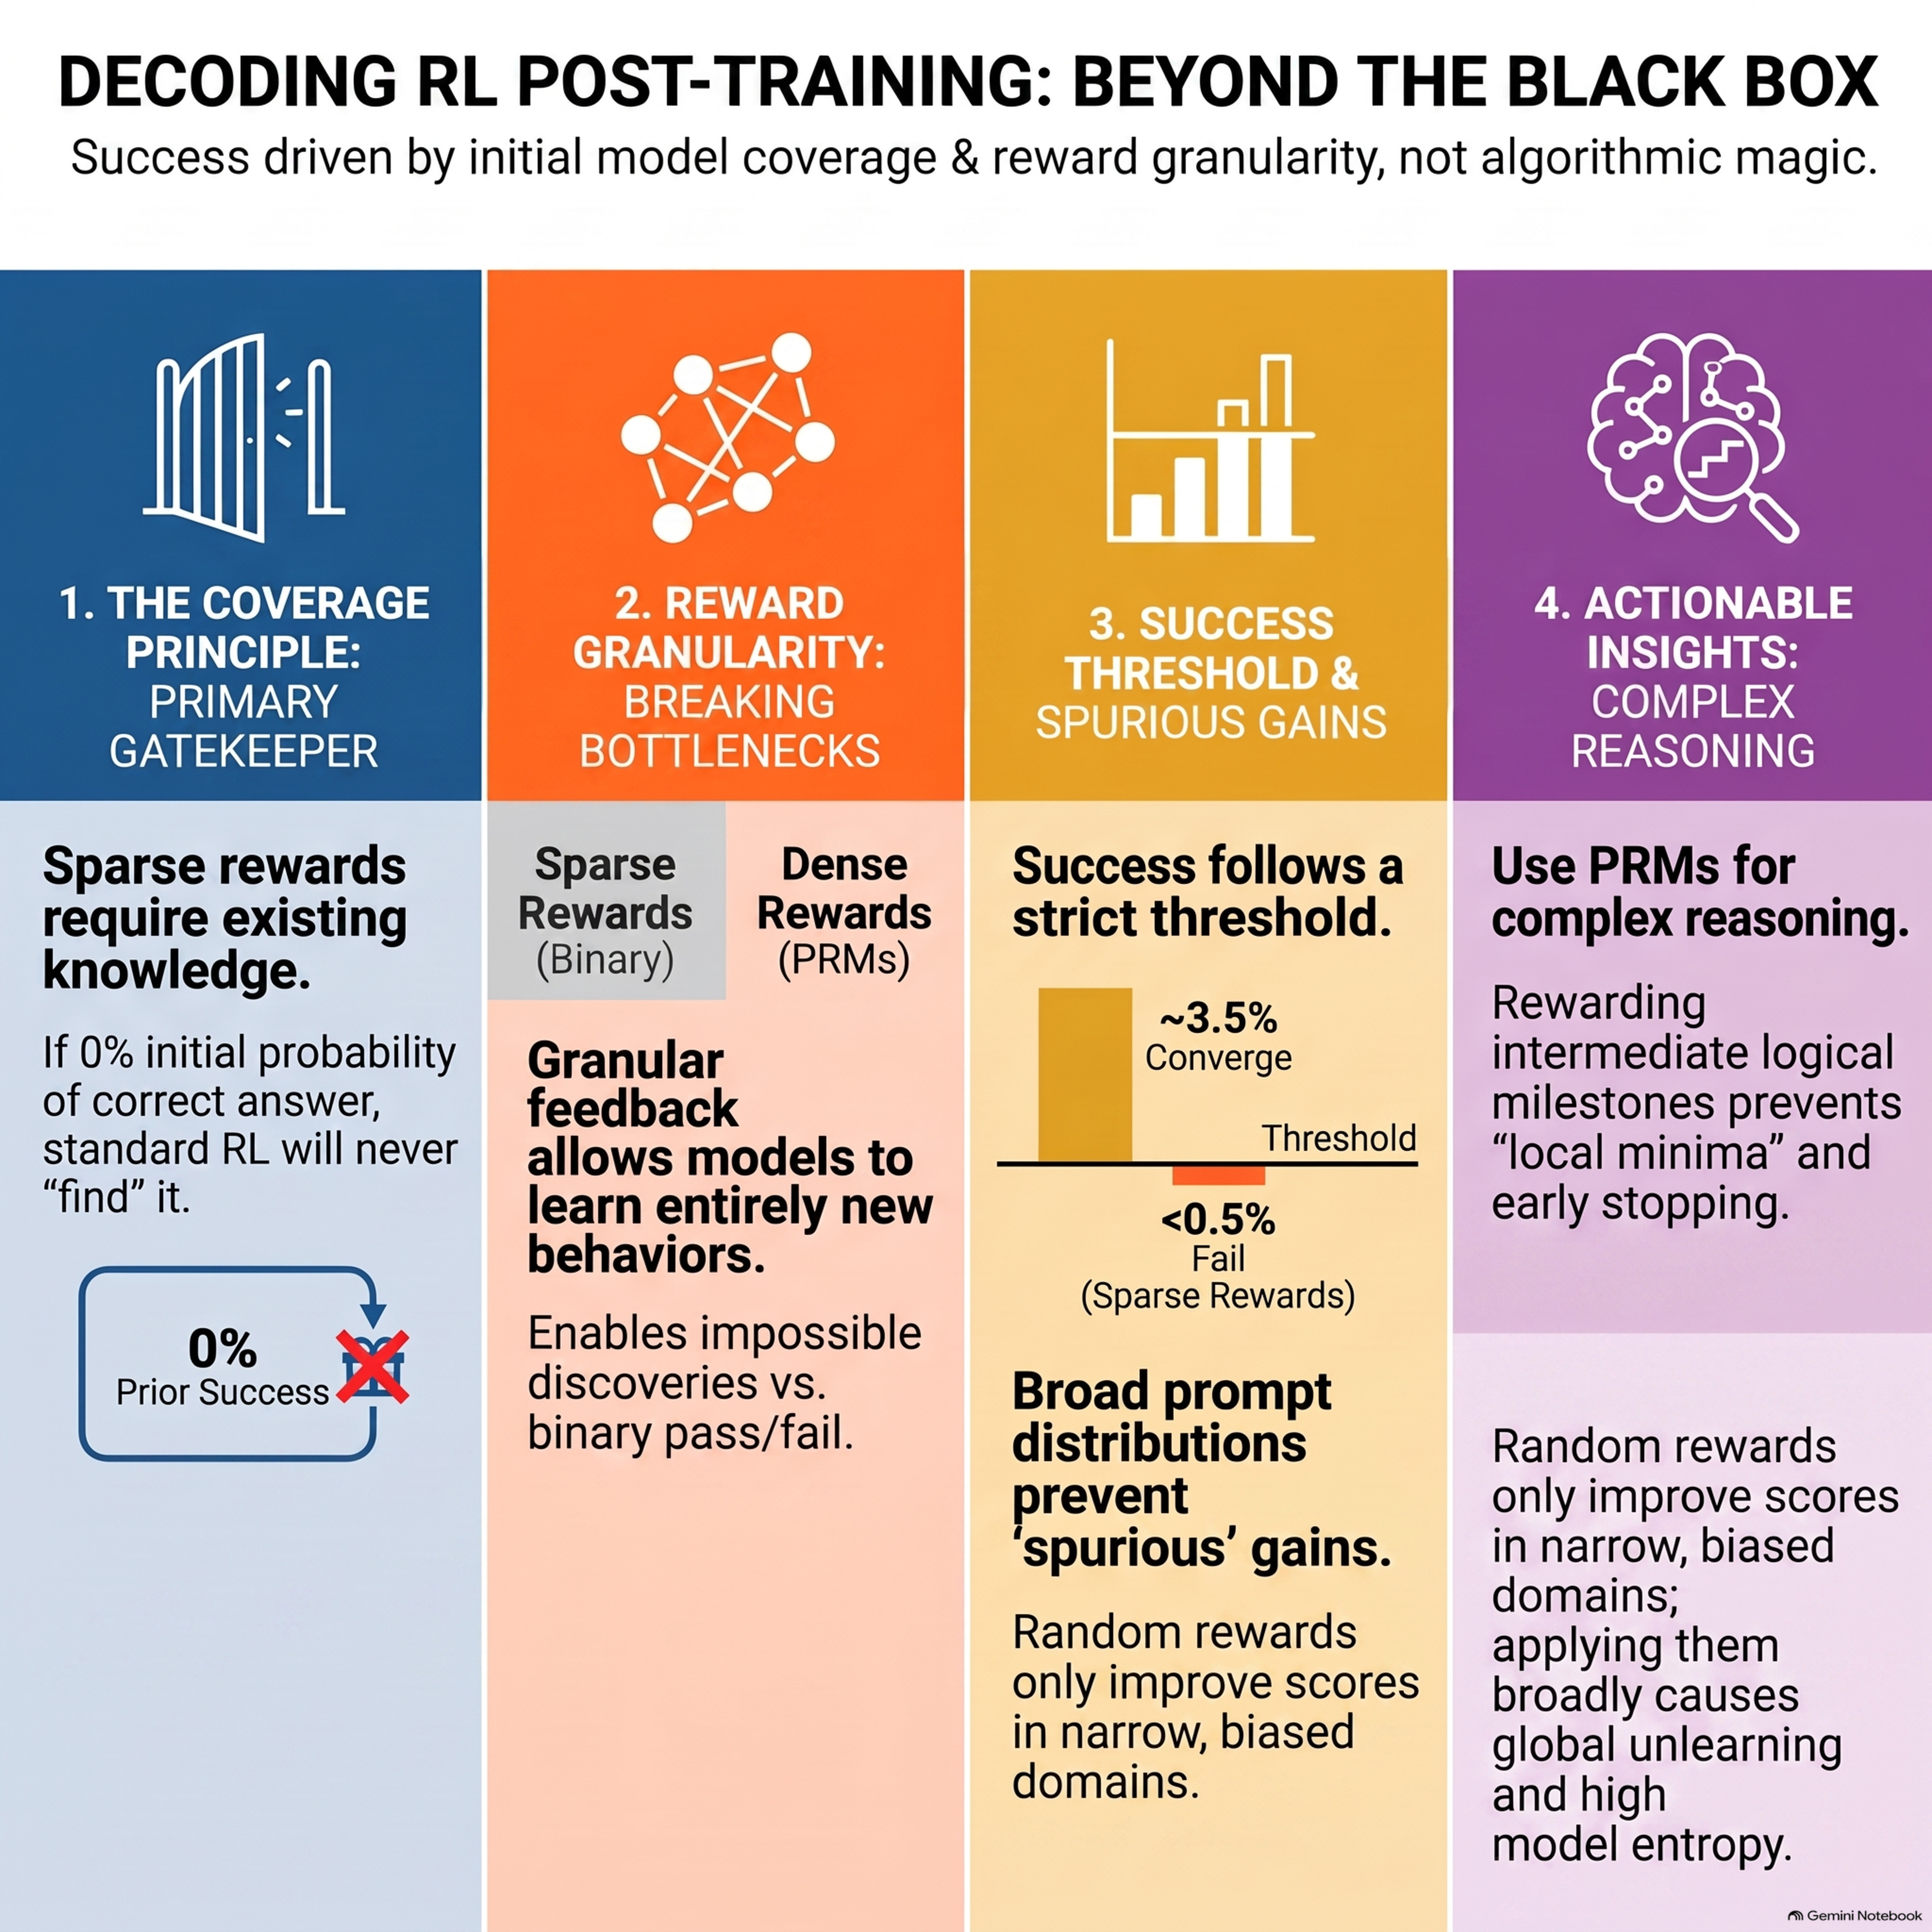
This paper deconstructs the mechanics of reinforcement learning (RL) post-training for large language models to determine how different factors influence model performance. By utilizing a controlled "sandbox" environment, the researchers demonstrate that standard sparse rewards typically fail unless the base model already possesses some prior knowledge of the desired behavior, a concept known as the coverage principle. However, the study reveals that dense reward signals, such as process reward models, can successfully teach models entirely new behaviors that were previously absent from their distribution. The authors also clarify that the controversial phenomenon of spurious or random rewards only improves performance under narrow prompt distributions, whereas broad distributions lead to global unlearning and increased entropy. Ultimately, the work aims to transform RL post-training from a "black box" into a predictable and interpretable optimization process by isolating the roles of base distributions, reward granularity, and dataset breadth.
Website: podcasters.spotify.com
