
H-Spec: Parallel Speculative Decoding Without a Drafter-Side KV Cache
· 22 min
Show notes
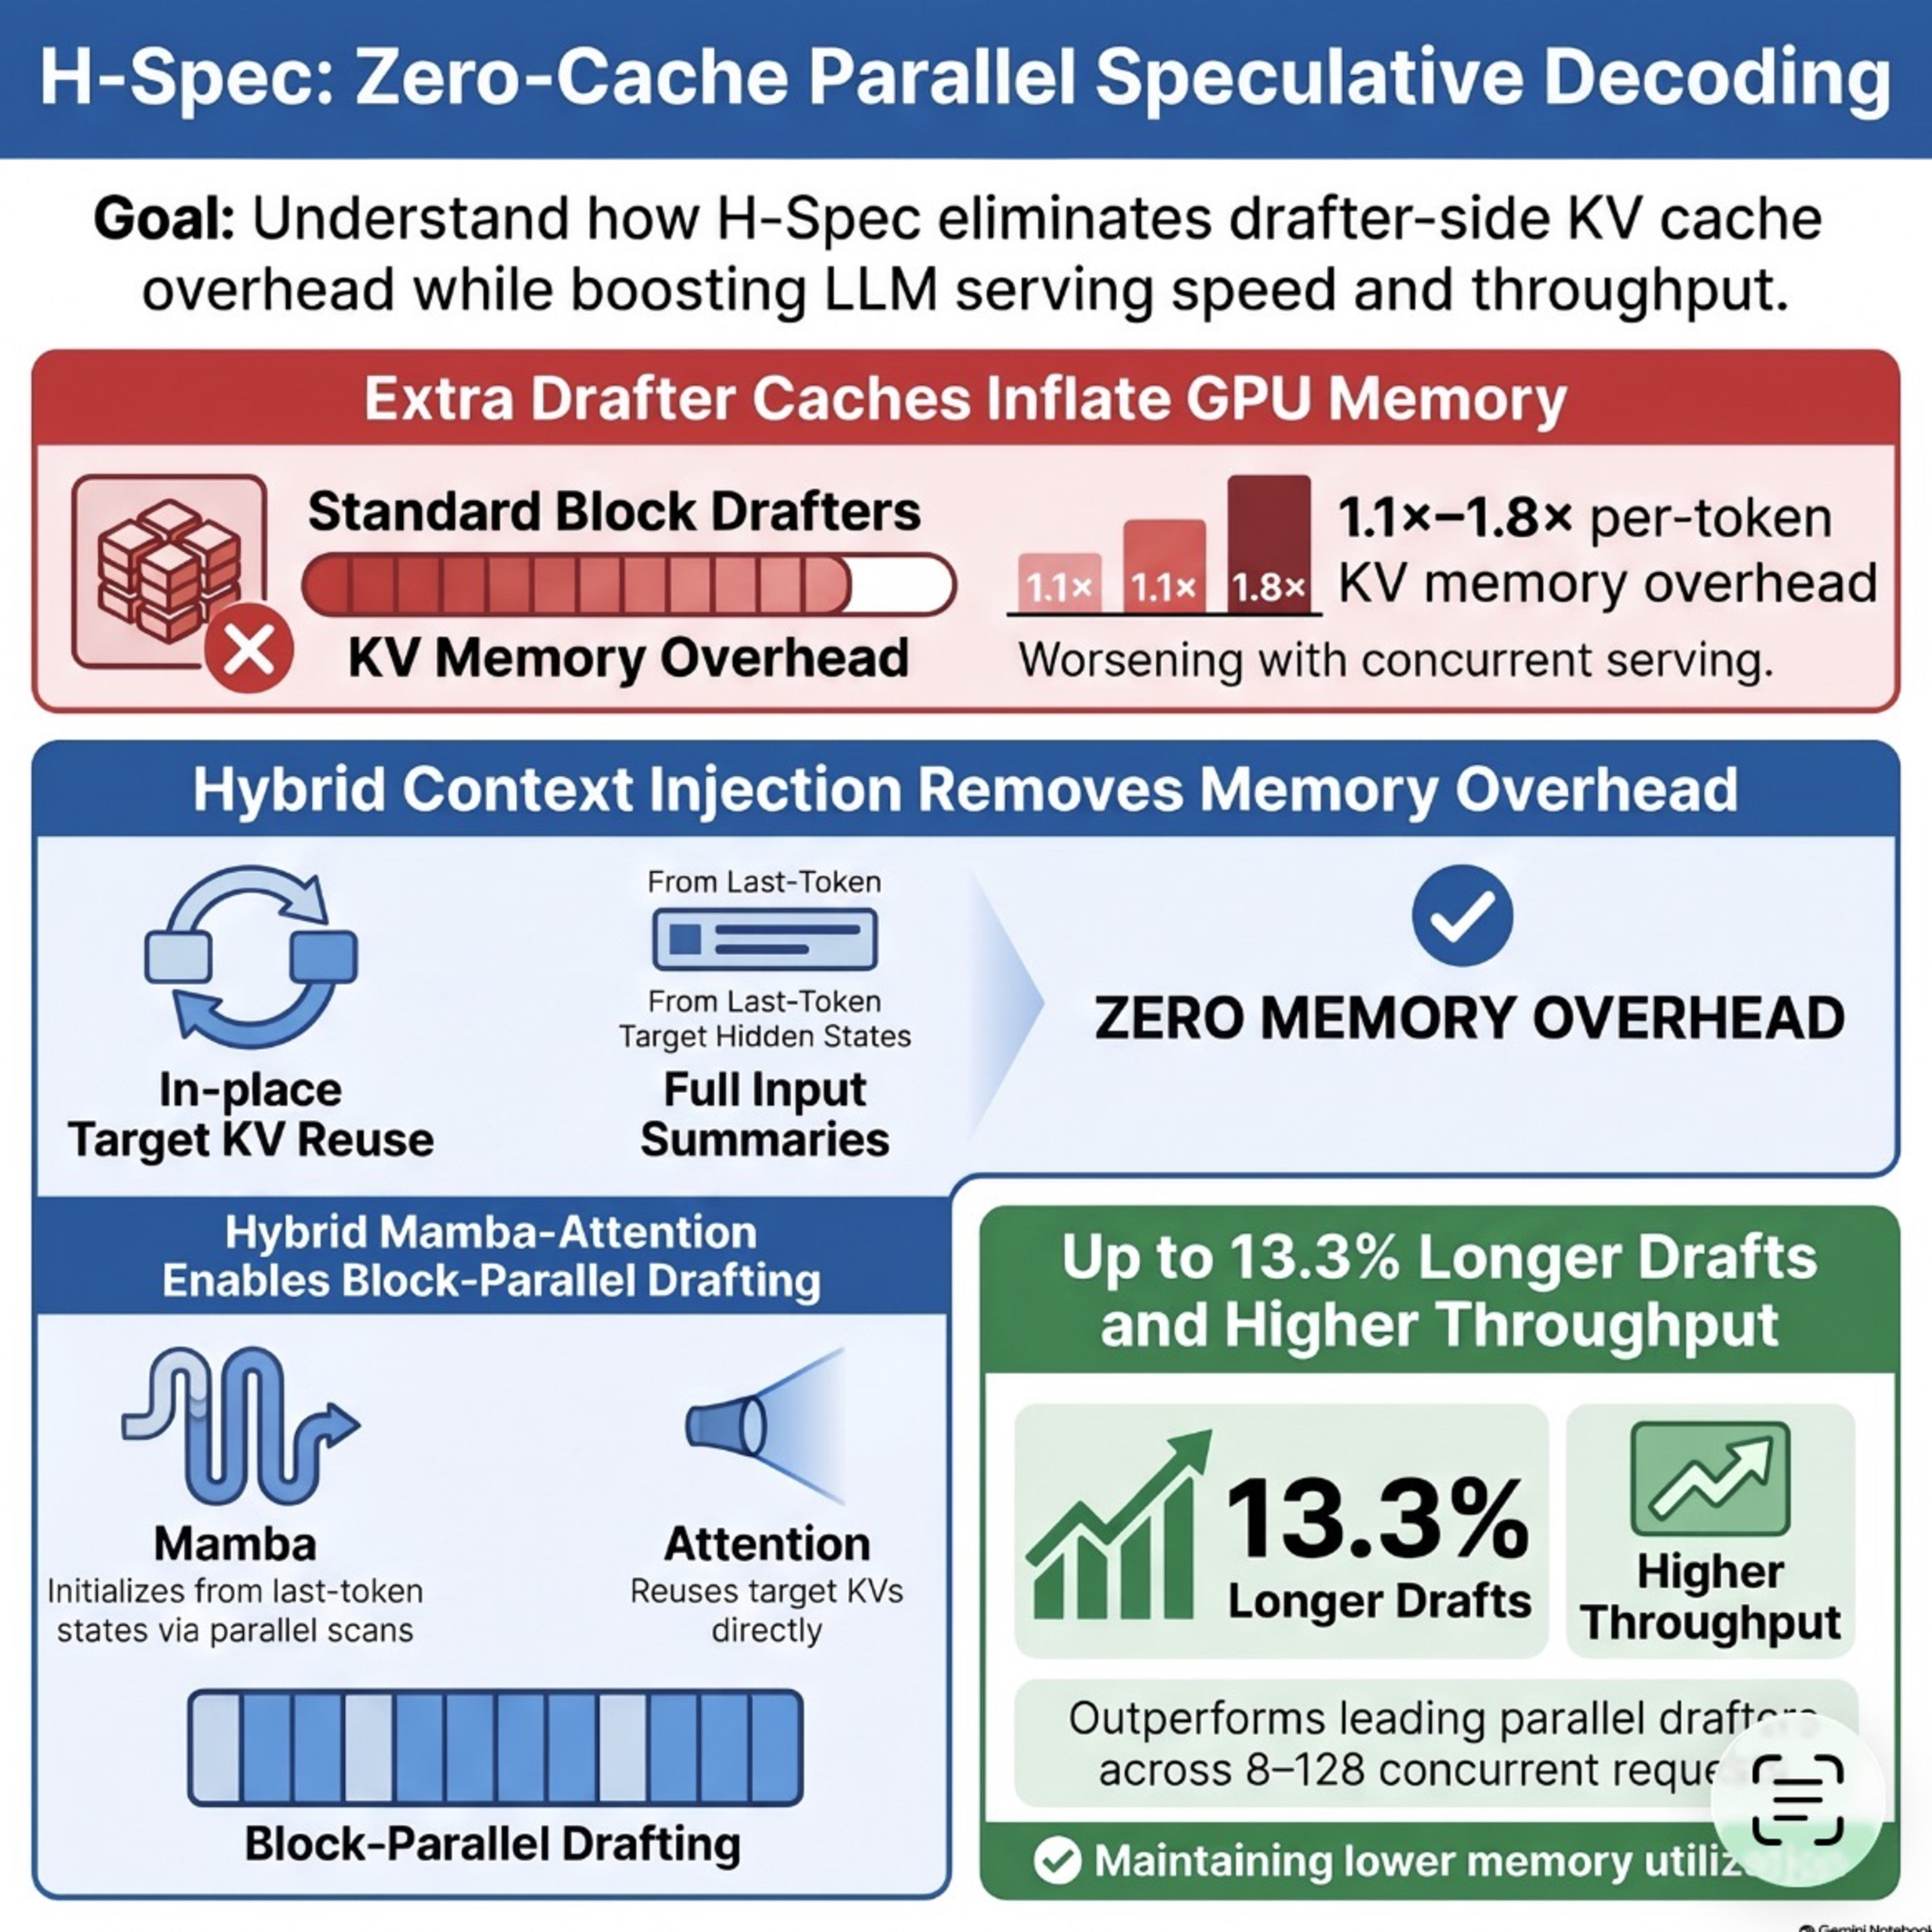
H-Spec is a novel parallel speculative decoding framework designed to accelerate large language models by eliminating the memory-intensive drafter-side Key-Value cache used by traditional block diffusion methods. Instead of projecting hidden states into a separate cache at every input position, it uses a hybrid target-context injection approach that combines in-place target KV reuse with the target model's hidden states from solely the last input position. This architecture leverages a Mamba-attention parallel drafter, where Mamba modules initialize from the last-token hidden states using a parallel scan, while attention modules directly consume the target KV cache. Evaluations demonstrate that H-Spec improves both mean accepted length and inter-token latency speedup across diverse tasks while achieving superior serving throughput and lower KV cache utilization under concurrent workloads compared to existing baselines.
Website: podcasters.spotify.com
