
Note dell’episodio
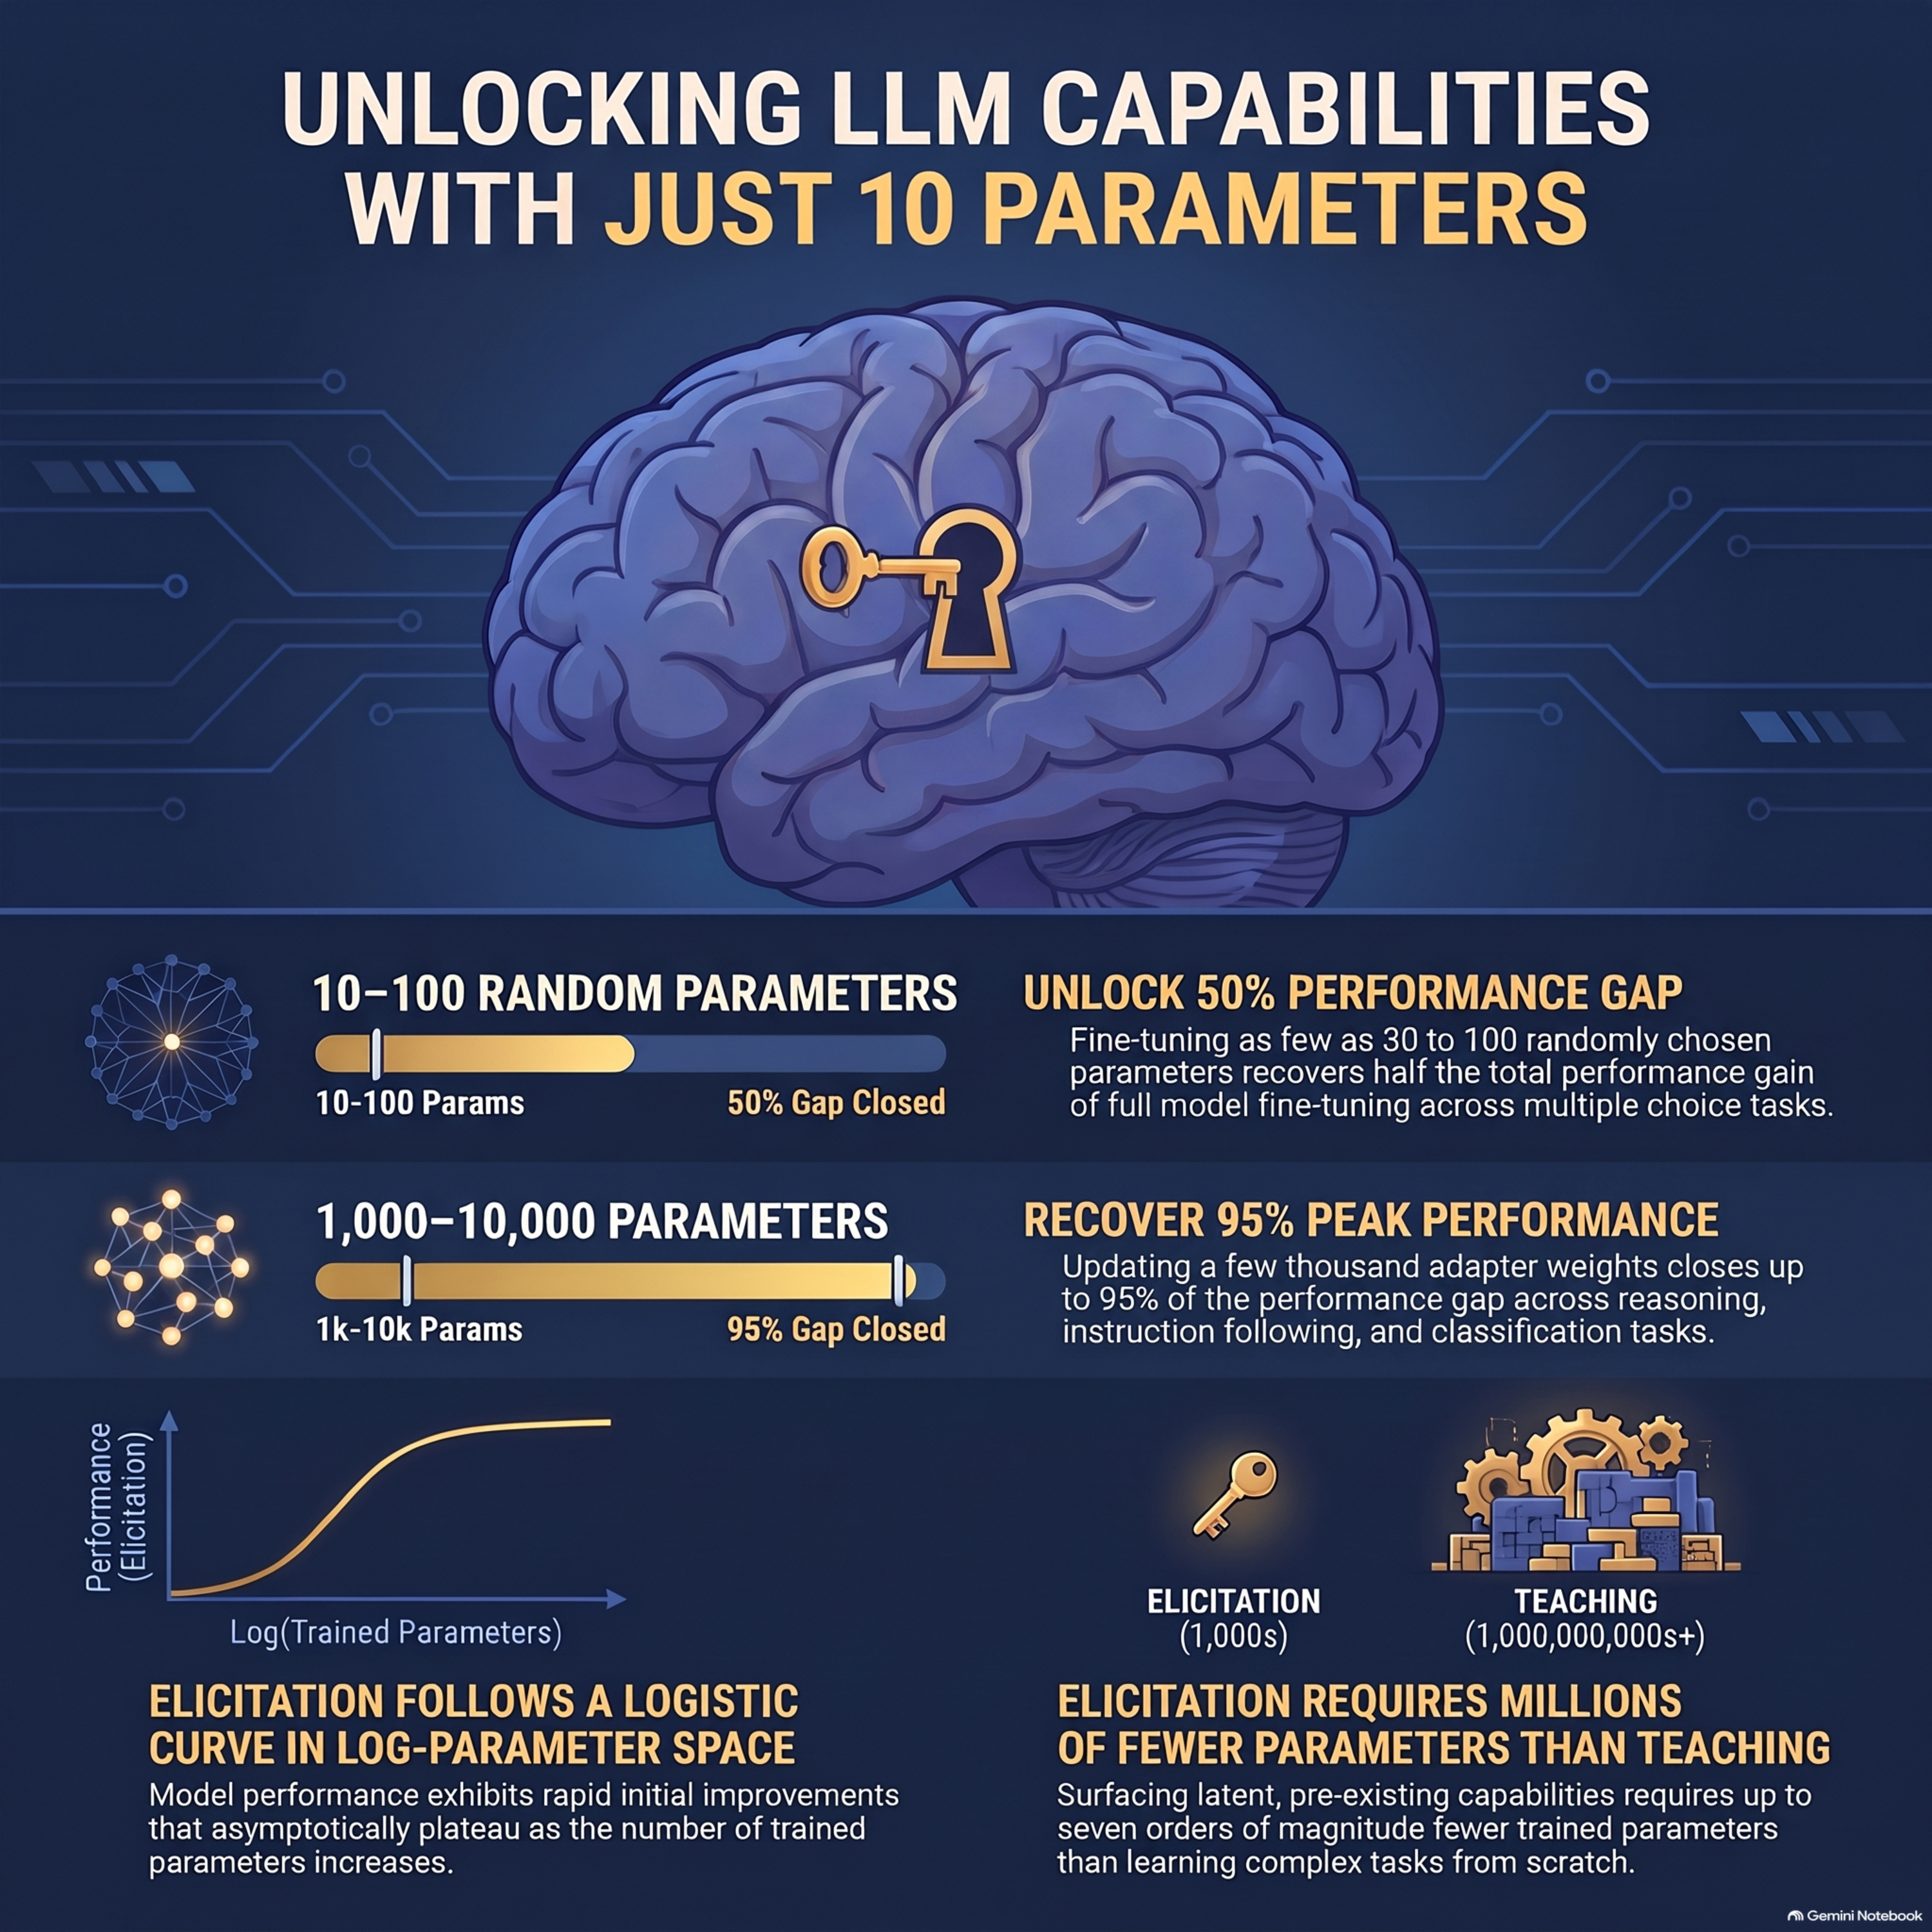
This paper investigates how large language models unlock latent capabilities through fine-tuning, reframing the process as an information-constrained problem. By analyzing parameter-efficient fine-tuning using randomly chosen parameters, the authors demonstrate that training a tiny fraction of a model's weights—often as few as tens to thousands—can recover the vast majority of its full performance gap. This behavior follows a consistent logistic scaling relationship across various tasks, model sizes, and families, independent of specialized search methods. Furthermore, the study applies Rissanen's Minimum Description Length (MDL) principle to distinguish true capability elicitation from teaching new skills, offering insights that can improve capability forecasting and safety evaluations.
Sito web: podcasters.spotify.com

