
Poznámky k epizodě
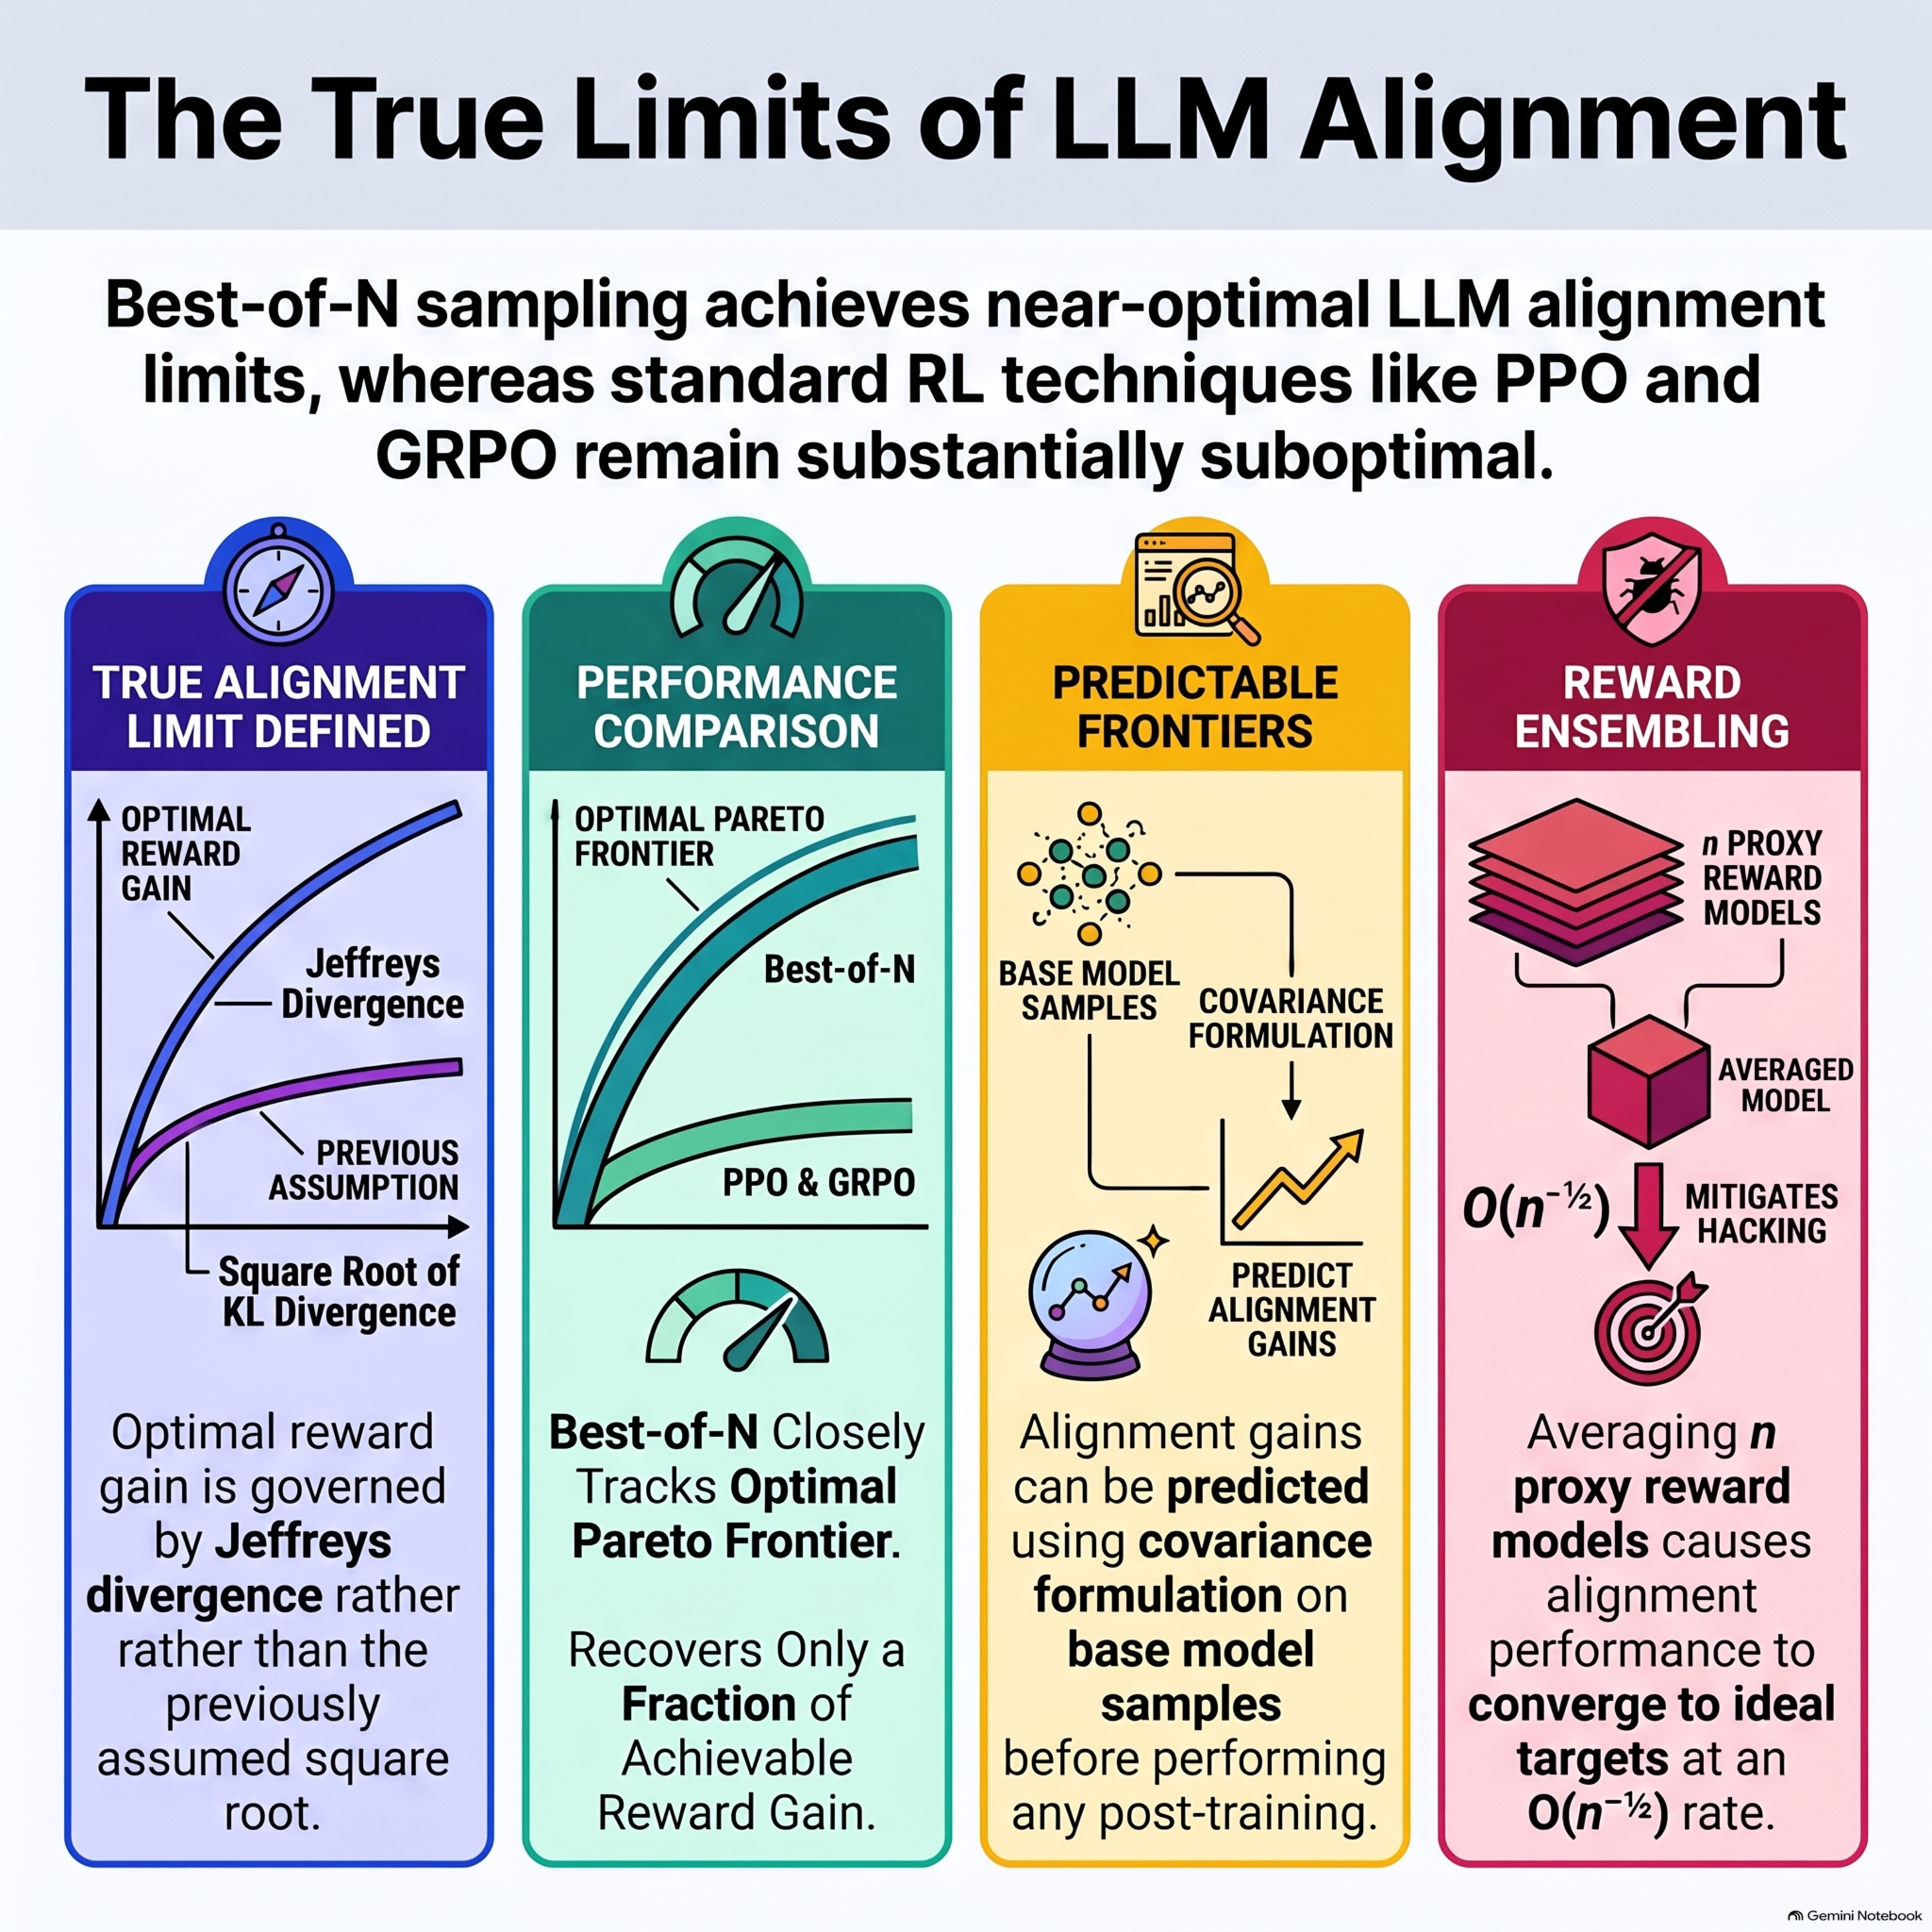
This paper investigate the fundamental limits of language model alignment by establishing exact theoretical boundaries for reward improvement under a KL-divergence constraint using Jeffreys divergence and a computable covariance estimator. They demonstrate that best-of-N sampling closely approaches this theoretical Pareto frontier, whereas gradient-based methods like PPO and GRPO remain suboptimal. Additionally, the literature analyzes how proxy reward errors drive performance degradation and reward hacking, while proving that reward ensemblingsuccessfully mitigates these issues at a convergence rate of O(n⁻¹ᐟ²).
Web: podcasters.spotify.com