
Show notes
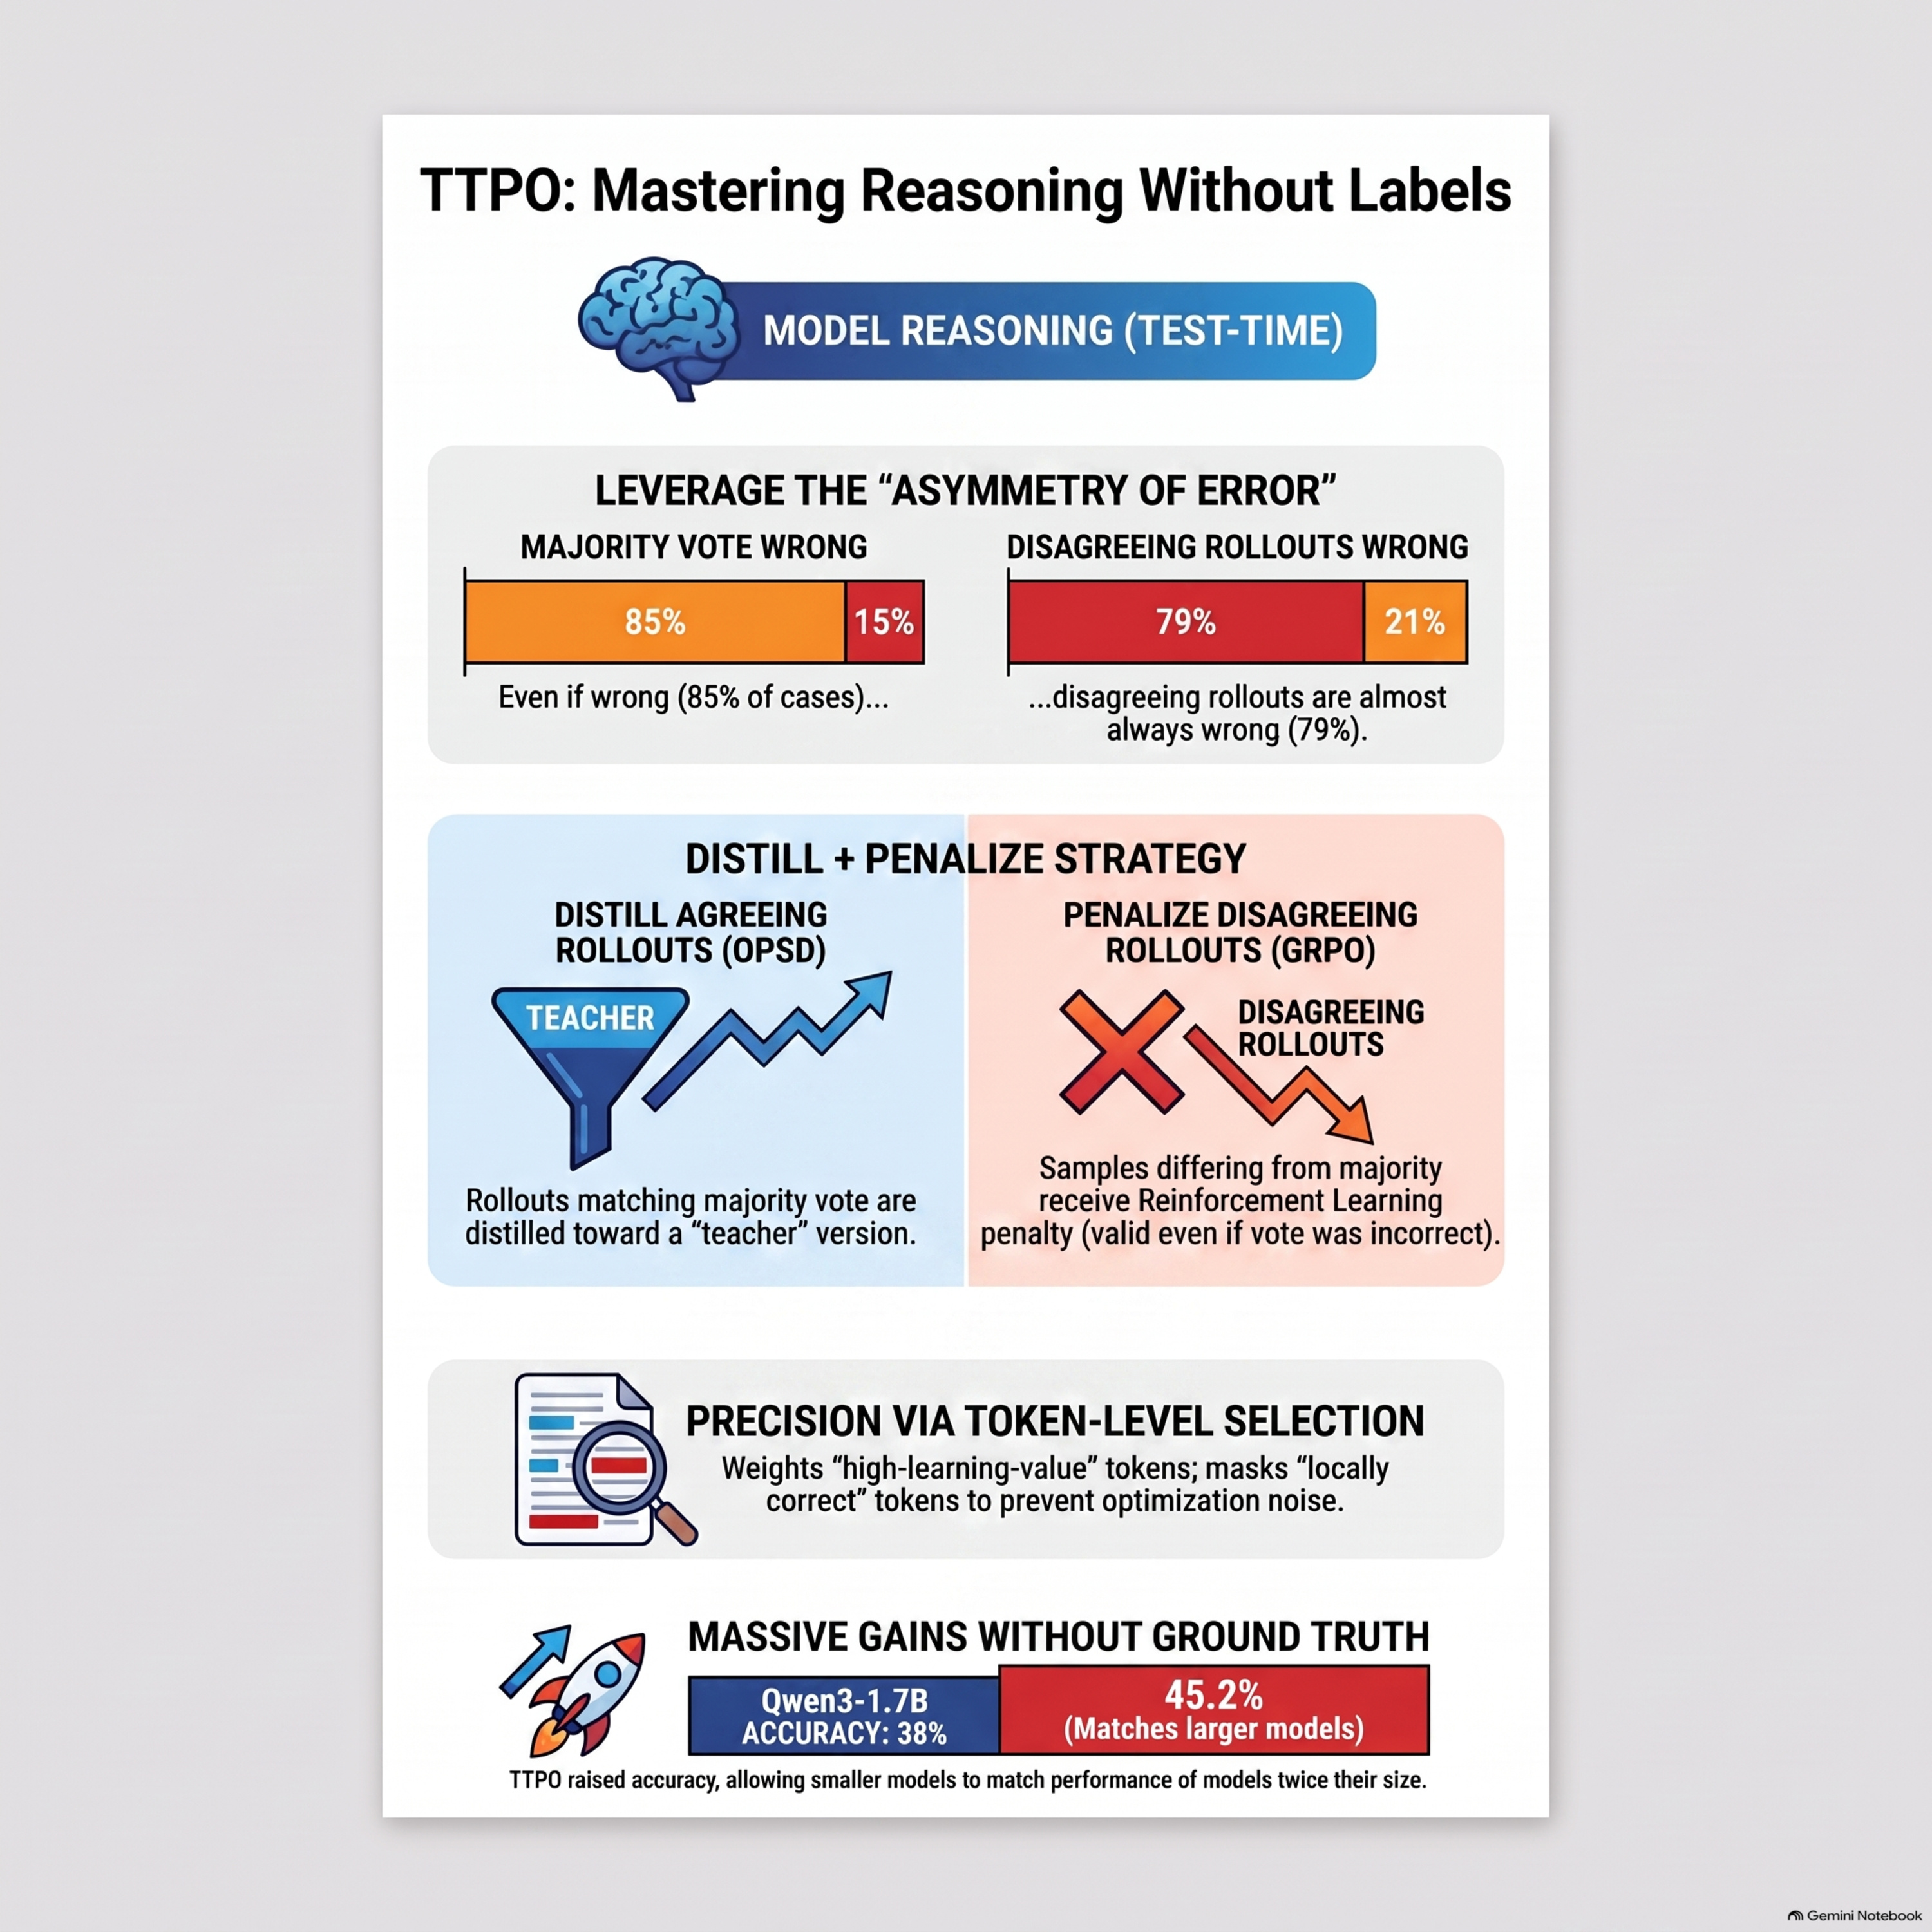
This paper introduces Test-Time Policy Optimization (TTPO), a novel method for improving the mathematical reasoning of large language models without using ground-truth labels. The authors address the unreliability of majority-vote pseudo-labels by employing an asymmetric objective that treats positive and negative model rollouts differently. Specifically, it uses on-policy self-distillation to refine trajectories that agree with the majority and Grouped Reinforcement Learning to penalize those that disagree. This design is enhanced by token-level selection, which focuses learning on informative positions while masking out confident errors and already-mastered content. Experimental results demonstrate that TTPO matches the performance of label-supervised methods and enables a self-evolving cycle where the model's improvements lead to higher-quality training signals. Ultimately, the framework significantly boosts accuracy on competition-level benchmarks and exhibits strong cross-task generalization.
Website: podcasters.spotify.com